No vendor is going to tell you that your data is not ready for their product. It would cost them the sale, and in fairness they usually cannot tell from a demo anyway.
So here is the piece nobody selling you something has an incentive to write. AI donor tools reason over what you have already recorded. If the records are thin, stale or inconsistent, the tool does not fail loudly. It produces confident, well-presented recommendations built on incomplete information, which is considerably worse than producing nothing, because people act on it.
This is a donor data readiness diagnostic you can run in an afternoon, plus a realistic fixing plan for one quarter.
Quick answer: Most nonprofits have enough data for AI tools to help, and worse data than they think. The blockers are empty contact reports, inconsistent gift coding and context trapped in inboxes. Run the fifty-donor test below. If you cannot answer three basic questions for most of them, fix inputs before buying anything.
What you are getting ready for. Data readiness is only worth the effort if something consumes the result, and the tools that do are donor intelligence layers: they read your existing records and return a ranked list of who to contact and why. Screening tools, which go looking for people you do not have, care far less about the state of your file. So passing the test below matters most if the first is what you are heading towards. Best AI donor intelligence tools covers the options.
The fifty-donor test
Everything else in this article is detail. This is the test.
Take your top fifty donors by lifetime value. For each one, using only what is in your systems and not your memory, answer:
- When did we last have a real conversation with this person, and what was said?
- Do we know why they give, in any recorded form?
- What is supposed to happen next with this relationship?
Score honestly. Memory does not count, because the tool cannot read your memory and neither can your successor.
Forty or more answerable on all three. Your data is in good shape. An intelligence layer will produce useful output quickly.
Twenty-five to forty. Typical, and workable. You will get real value, with gaps. Fix inputs alongside adopting a tool rather than before.
Under twenty-five. Do not buy anything yet. A tool pointed at this file will produce recommendations that look authoritative and rest on very little. Spend a quarter on the fixes below.
What actually blocks these tools
Five things, in order of how often they are the problem.
1. Contact reports that record attendance, not content
The most common blocker by a distance. A CRM full of entries reading “called”, “coffee”, “left message” is a log of activity with no information in it.
What good looks like: what was discussed, what they said about the organisation, any personal circumstances relevant to timing, what you agreed to do next. Three or four sentences. Nothing elaborate.
Why it blocks: every signal that matters, intent, hesitation, life events, informal commitments, lives in the content of conversations. A tool reading “coffee, positive” learns nothing.
2. Context trapped where the tool cannot reach
The conversation is in an inbox. The proposal is on somebody’s drive. The note about the donor’s illness is in a text message.
Why it blocks: even tools that read email are usually reading a connected organisational account. Personal inboxes and individual drives are invisible, and they are where most nonprofit context actually lives.
What good looks like: an organisational expectation that relationship-relevant material gets into the system of record, and a shared drive rather than personal ones.
3. Inconsistent gift coding
Campaign codes that changed three times, appeal codes applied sometimes, funds that mean different things depending on who entered them.
Why it blocks: trajectory analysis is one of the strongest predictive signals available, and it needs comparable gifts across years. If the same annual appeal is coded four ways, the trajectory is invisible.
What good looks like: a documented coding scheme, applied consistently going forward. Retrospective cleanup is a nice-to-have; consistency from today is the requirement.
4. Duplicates and identity fragmentation
The same person as three records: one from an event, one from an online gift, one from the newsletter list.
Why it blocks: it fragments giving history, which breaks both tenure and trajectory. A twelve-year donor split across three records looks like three casual donors, and their planned giving signal disappears entirely.
What good looks like: deduplication before you connect anything, and a rule about how new records are created.
5. Stale contact data
Old addresses, dead emails, no phone.
Why it blocks: less than the others, honestly. It limits action rather than analysis. The tool can still tell you who to call, you just cannot call them.
What does not block you, despite what you have been told
Worth saying, because data-readiness advice tends toward the counsel of perfection and stops people acting.
You do not need a perfectly clean database. Every real nonprofit database has mess in it. The question is whether the signal-carrying fields are usable, not whether everything is pristine.
You do not need years of history. Three years of consistently coded giving supports trajectory analysis. Twenty years of inconsistent coding does not.
You do not need to fix everything first. Fix contact reports and coding, which are input habits and change immediately. Historic cleanup can run in parallel forever.
You do not need a new CRM. This is the expensive misdiagnosis, and we cover it properly in new CRM or better intelligence. Bad data in a better database is bad data.
The one-quarter fixing plan
Weeks one and two: measure. Run the fifty-donor test. Count duplicates. Pull a year of gifts and look at the coding. Write the numbers down, because you will want them in three months.
Weeks three and four: fix the inputs. This is the highest-return work and it costs nothing.
- Agree what a contact report must contain. Four sentences, four prompts: what was discussed, what they said, anything personal and relevant, what happens next.
- Document the coding scheme and put it where people enter gifts.
- Agree where relationship context lives, and make it somewhere the organisation owns.
Weeks five to eight: deduplicate and consolidate. Merge duplicates. Move what you can out of personal drives and inboxes into shared systems. Tedious, and it makes everything after it work.
Weeks nine to twelve: backfill selectively. Not the whole database. Your top hundred relationships. For each, get the basics recorded: why they give, last real conversation, what should happen next. This is the same exercise as a donor handover and it has the same value: it survives whoever leaves.
Then re-run the fifty-donor test. Most organisations move up a band in a quarter, which is enough to change the answer on whether to buy.
What to expect once you connect something
Weeks one to two: it reads your history and looks unimpressive. Normal. It is building context.
Weeks three to six: the first genuinely useful surfacing, usually something obvious in hindsight that nobody had spotted. This is the point at which people start trusting it.
Months two to six: value tracks record quality closely. Teams who kept up the contact report habit see it compound. Teams who reverted plateau, which is the most common failure mode and it is a management problem rather than a software one.
If you are choosing a tool, our best AI donor intelligence tools roundup and the moves management guide are the place to start. And before you connect anything to donor records, run through what to ask an AI vendor first.
What donor data actually looks like when a vendor first connects to it
Vendor readiness checklists describe a database nobody has. Here is what the connection usually finds, and which of it genuinely matters.
History that predates the current database
Most organisations have migrated CRM at least once, and migrations lose things quietly. Gifts before the switch often arrive as a single opening balance rather than individual transactions, which means a model reading “first gift date” gets the migration date, not the truth. Check one long-standing donor manually before believing any recency analysis. If the earliest gift for a forty-year supporter is dated 2019, you have found a migration boundary and every recency score in the system is measuring the wrong thing.
Soft credits, which break attribution in both directions
A gift from a donor-advised fund, a family foundation or a matching employer arrives from one legal entity while the relationship belongs to another. Whether your database records the individual, the vehicle, or both with a soft credit determines whether a model sees a lapsed donor or an active one. This is the single most common cause of a prediction that looks obviously wrong to a gift officer, and it is a data structure problem rather than a model problem.
Households, which most systems handle badly
Two people, one gift, one address, sometimes two records, sometimes one. Ask what a tool does with household relationships before it runs anything, because deduplicating a couple into one record destroys the individual giving history and leaving them separate double counts your donor numbers. Neither answer is wrong; you need to know which one you have.
Coding that changed meaning without changing name
Campaign and appeal codes get reused. A fund code that meant one programme in 2021 and another in 2024 is worse than a missing code, because it is confidently wrong and nothing flags it. Before connecting anything, pull the list of codes used in the last five years and have the person who has been there longest read it. That single hour finds more real problems than any automated data quality report.
Contact reports that record attendance, not content
“Coffee with donor, went well” is a diary entry. It tells a tool that contact happened and nothing about what was said, what was asked for, or what the donor cares about. Systems that read notes are only as good as the notes, and most organisations have years of attendance records rather than substance. This one is fixable going forward and unfixable backwards, which argues for changing the note template today regardless of whether you buy anything.
What none of this blocks
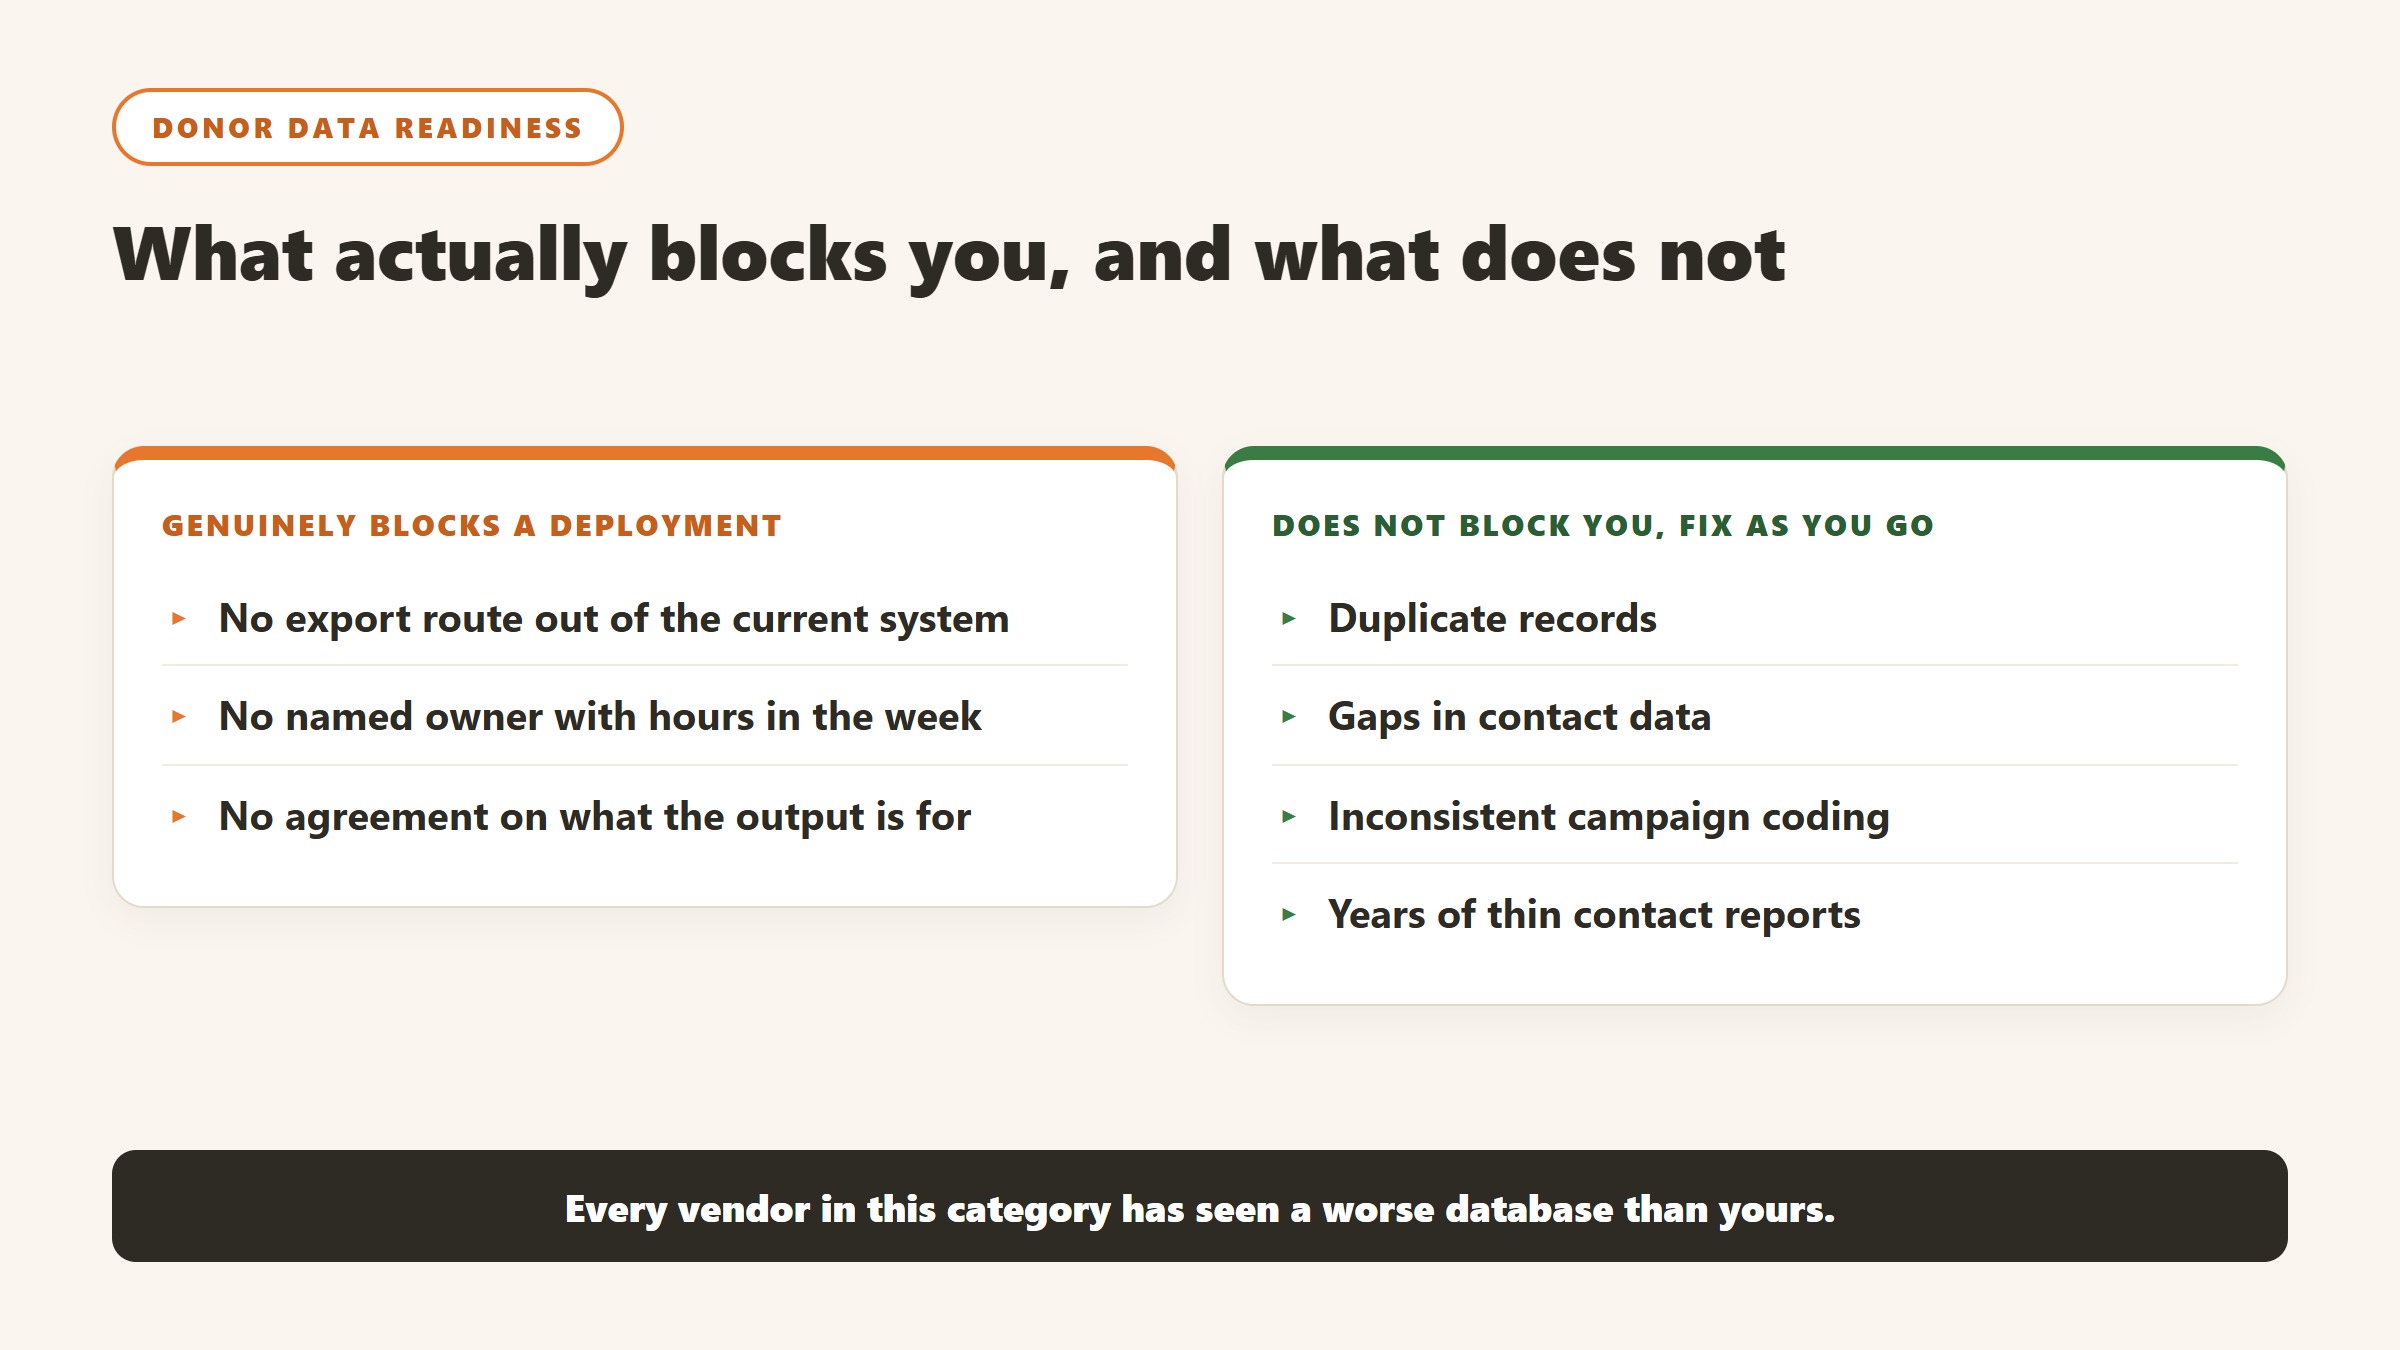
Imperfect data is not a reason to wait. Duplicates, gaps and inconsistent coding are the normal condition of a fundraising database and every vendor in the category has seen worse than yours. What genuinely blocks a deployment is different and much narrower: no export route, no owner, or no agreement about what the output is for. Fix those three and start; fix the coding as you go.
A sequence that works, in the order it has to happen
The order matters more than the choices. Most of the expensive mistakes in this category come from doing step four before step two.
First, name the owner and get the hours
Every system in this category rewards an owner and punishes shared responsibility. Before evaluating anything, name the person whose job description will include it and confirm where the hours come from. If the answer is “we will fit it in”, the project has already failed and the software will be blamed. This is not a formality; it is the highest-correlation predictor of whether a nonprofit technology purchase delivers.
Second, establish what you can export
Pull a real export from your current system before you shortlist. Not a screenshot of the export screen, the actual file. What comes out, in what format, with which fields, is the constraint every later step inherits, and it is common to discover that the thing you assumed was in the database is in somebody’s spreadsheet. Two hours here reprices the whole project.
Third, run a small test with real records
Fifty to two hundred of your own records, chosen to include the messy ones: a household with two donors, a lapsed major donor, a donor-advised fund gift, a failed recurring schedule. Have the person who knows those donors best read the output. Their reaction in ten minutes is worth more than a month of vendor references, and it is the only stage that reliably catches a tool that is confidently wrong about your particular data shape.
Fourth, decide the meter before you decide the vendor
Constituent-priced, seat-priced, revenue-priced and contact-priced platforms produce wildly different bills for the same organisation. Salesforce is free at ten seats and $14,400 a year at thirty. Little Green Light is $45 a month at 2,500 constituents and rises with the list regardless of headcount. Work out which of your numbers is growing fastest, then shortlist the vendors whose meter is the one growing slowest.
Fifth, and only now, negotiate
With an owner, a known export, a tested output and a chosen meter, a quote is a comparison. Without them it is a guess, and the vendor is better at guessing than you are. The order is the leverage.
Where the figures on this page come from
Every price quoted here was read from the vendor’s own pricing page on 4 September 2026, not from an aggregator or a review site. That distinction matters more in this category than in most, because nonprofit software pricing changed materially over the past year and a great deal of what circulates online describes packaging that no longer exists.
The pages we read
Little Green Light publishes every constituent band from $45 a month. Salesforce Nonprofit Cloud publishes $60 per user per month with ten licences free under Power of Us. Bloomerang publishes $125 a month for the CRM with other products priced separately. Keela publishes every contact band from $164 a month. Dataro publishes $15,000 a year plus ten cents per active donor on a page that is not linked from its own navigation. Blackbaud and Virtuous publish no figures at all.
What we do not do
We do not carry a figure we cannot source to the vendor. Where a number circulates widely and cannot be traced to a vendor page, we say so and withdraw it rather than repeating it with a hedge, and we have withdrawn our own published figures on that basis more than once. Where a vendor confirms an unpublished price directly to us, it is attributed as confirmed by the company rather than presented as a public rate.
Why every figure carries a date
Keela raised every band by roughly 15 to 22% in under two weeks in late August 2026. Neon retired an entire tier structure. A pricing claim without a verification date is not checkable, and in this market it is usually wrong within a year.
The bottom line
Most nonprofits are readier than they fear and messier than they think, and the gap between those two is where the disappointment with AI tools comes from.
Run the fifty-donor test. It takes an afternoon and it will tell you more than any vendor demo, because it tests your organisation rather than the software.
If you score well, buy something. If you score badly, spend a quarter on contact reports and coding, which is free and changes the answer. And if a vendor tells you your data readiness does not matter, you have learned something useful about that vendor.
Written by
FazFaz is the founder of AIToolsBakery. Some tools here are tested hands on. Others are assessed from vendor documentation and pricing verified on the live page, and every review says which one it is. Sponsors can buy a position in a guide. They cannot buy the score, the criticism, or silence about a better option.
How we test and how we make money →Frequently Asked Questions