The scorecard
| Dimension | Score | What it rests on |
|---|---|---|
| Source citation and verifiability | 5.0 | Ten of ten narrative claims correct, each with a citation to a specific gift row |
| Refusal to fabricate | 5.0 | Two adversarial tests, including a deliberately leading question. Held both times |
| Actionability | 4.5 | The Action Center gives a ranked list with the reason attached, which is the product’s best idea |
| Getting your data in | 4.5 | Five native integrations, CSV, and document upload. No migration required |
| Breadth shipped today | 4.0 | Two significant features are still to come |
| Value for money | 5.0 | A free plan that does not expire, $99 a month for a single fundraiser, and $4,788 a year covering five people at $80 each per month, against a category that mostly will not publish a price at all |
| Overall | 4.7 |
Prefer to watch? Twenty minutes of Gratefully in action, walking through everything the tool does.
1. What Gratefully is, and where to find it
Gratefully is an AI donor intelligence platform built specifically for nonprofits. It is not a CRM and it does not want to be one. It connects to the systems you already run, reads across your donor data, your email and your documents, and every morning hands your team a ranked list of who needs attention today with the reason attached to each name.
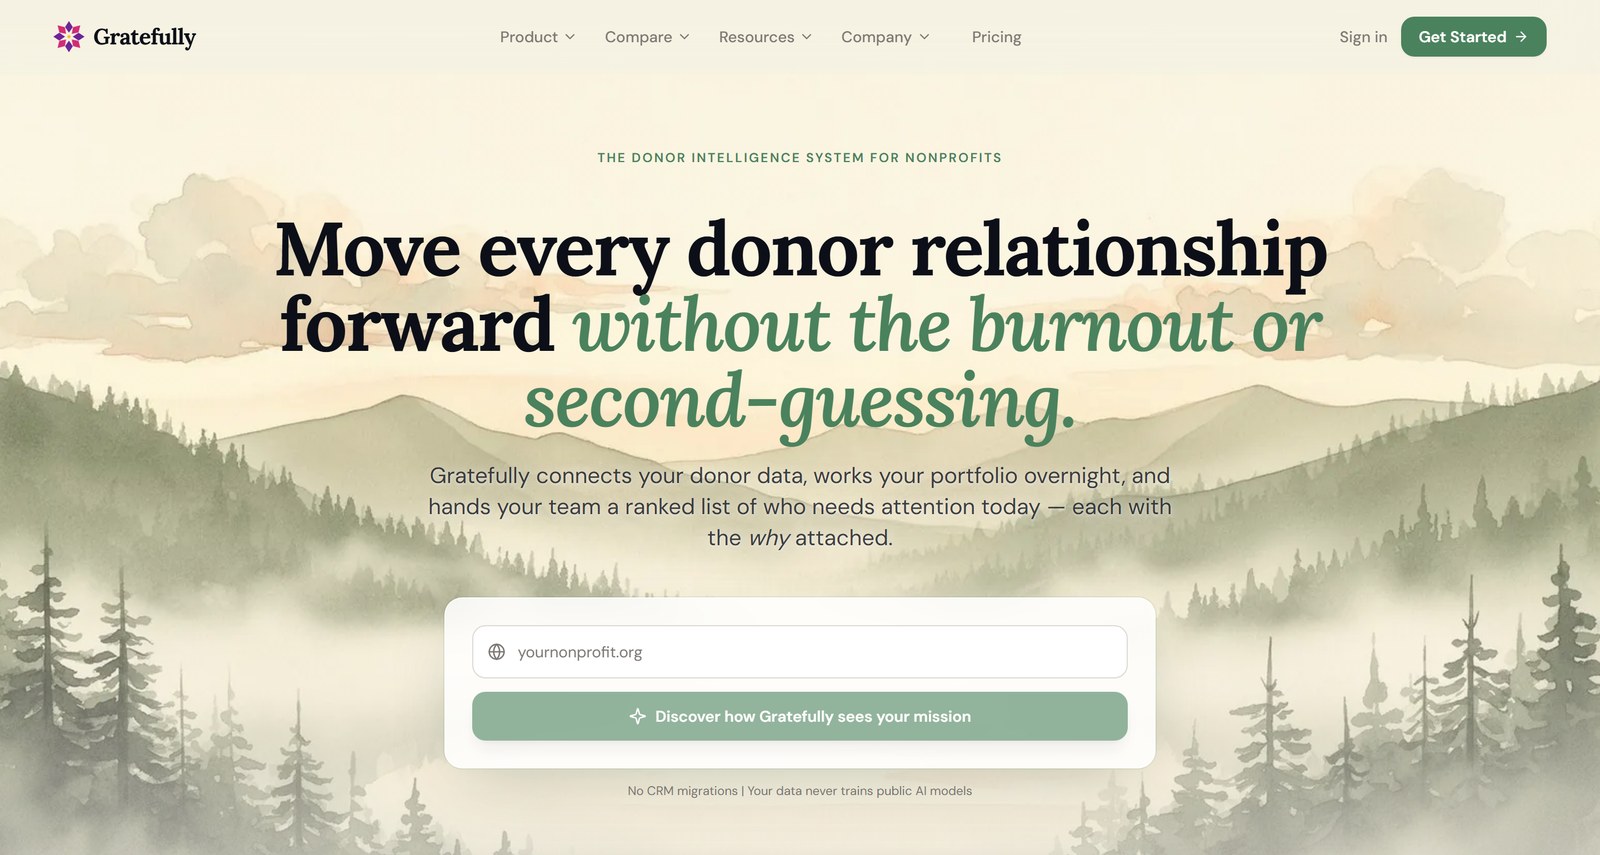
Their own one-line description is a fair summary of the pitch: “Gratefully connects your donor data, works your portfolio overnight, and hands your team a ranked list of who needs attention today, each with the why attached.”
You can see the product at gratefully.io. A few pages worth opening before a demo call, because they answer the questions buyers actually ask:
- Pricing, which unusually for this category publishes real figures rather than a contact form
- How it works and the Action Center, the daily ranked list that is the heart of the product
- Knowledge Graph, the structure everything else reads from
- Security and PII redaction plus their PII redaction whitepaper, which is the section your board will care about most
- Handover dossiers, aimed at the problem of a gift officer leaving and taking the relationship history with them
The rest of this review is what I found when I stopped reading their website and started using the product.
2. How we tested this, and what to know about the numbers
I want to be exact about what I did, because that is the only thing that makes a review like this worth reading.
This was ordinary trial access, not a vendor demo tenant. I signed in with a normal account on the four-week free trial Gratefully published at the time, in August 2026, which needed no credit card. The trial is now 14 days. Nobody at the company provisioned a curated workspace, staged a dataset or sat on a call steering me around the good parts. That matters for how you read everything below: what I saw is what any buyer sees in their first week, including the rough edges a sales engineer would have navigated around.
I separated what I tested from what I merely looked at, and held to it throughout. Tested means I supplied an input and judged the output, which covers the two fabrication attempts, the ten-claim citation audit and the arithmetic checks. Observed means the product or its seeded data already contained something and I read it, which covers the interface, the segments, the Action Center card types and the agent activity log. Where this review says a thing was tested, an input went in and a result came back. Everywhere else I have tried to say “the workspace showed” instead.
Two hands-on sessions, on 13 and 18 August 2026, both in a trial account on Gratefully’s own platform.
Sample data, not a real portfolio. Gratefully’s preloaded dataset, 27 donors and 72 gifts on the later session. This is the most important limitation in this review. Because the donors are synthetic, I cannot tell you whether Gratefully surfaces the right people, since there is no ground truth to measure against. What I could test, and did, is internal consistency, arithmetic, citation accuracy and behaviour at the edges. Those determine whether you can trust the output. They do not determine whether the ranking matches a good fundraiser’s judgement, and anyone telling you otherwise from a demo account is overreaching.
No CRM was connected, so I am describing the CSV and sample-data path rather than a live sync.
The pricing figures were read from gratefully.io/pricing on 22 August 2026 and cross-checked against the plan selection screen inside the product on the same day. Both matched. Gratefully has said further plans are coming, so treat these as correct on the date stated.
Nothing was sent. I deliberately left the email drafting flow alone, because drafting sits one click from sending and this is not my donor file.
What I did not test, so you know the edges of this: field mapping during a live CRM integration, the Categories section, tagging donors or segments from inside the chat, and Grace generating emails, strategy documents or reports. The first two I never reached, and the last two I avoided because they produce outbound material from someone else’s donor file. I will cover them in an update.
I am not a fundraiser, as stated at the top. Where the question was whether something is good fundraising practice rather than whether the software works, I have said so rather than pronounced.
Every verbatim quotation in this review is copied from the session transcript. Every figure I checked, I checked by hand against the table on the same screen.
See the disclosure at the foot of this article.
3. I am not a fundraiser, and that turned out to be the point
I do not run a nonprofit. I have never carried a donor portfolio, never made an ask, never sat in a gift officer’s chair at eight in the morning wondering who to call. By any normal standard I am the wrong person to review a donor intelligence platform.
I want to be honest about that up front, because it changes what this review can and cannot tell you. I cannot tell you whether Gratefully’s ranking of your donors matches what an experienced development director’s instinct would say. Nobody can tell you that from the outside, and anyone who claims to after a week with a demo account is selling you something.
What I can do is something a fundraiser evaluating this on a busy Tuesday probably will not: I can take the product’s central claim, which is that every answer it gives is grounded in your actual data and cites its source, and I can try very hard to break it.
That is what I did. I spent two sessions inside Gratefully, on 13 and 18 August 2026, working with the sample dataset it ships with. I tried to make it tell me about a donor who does not exist. I asked a deliberately leading question designed to invite an invented answer. I took a paragraph it had generated about a donor and checked every single factual claim in it against the gift table on the same screen, line by line, with a calculator.
It held. All of it. And somewhere around the seventh verified claim I stopped taking notes like a sceptic and started taking them like someone who had found something.
That is the honest emotional arc of this review and I am not going to pretend otherwise. But an impression is not evidence, so the rest of this piece is the evidence, and you can decide for yourself whether my reaction was proportionate.
What I was working with
Both sessions ran against Gratefully’s preloaded sample data rather than a real donor file. On the 18 August session that was 27 donors and 72 gifts. The earlier staging session had a larger synthetic set.
This matters and I will keep saying so. With synthetic data I cannot assess whether Gratefully surfaces the right donors, because there is no ground truth to compare against. What I can assess is internal consistency, arithmetic, and behaviour at the edges: does the summary agree with the table, does the narrative agree with the record, does it refuse when it should refuse. Those are the things that determine whether you can trust what it tells you, and they are exactly the things most reviews never check.
4. What Gratefully actually is
The single most common misunderstanding I saw when researching this category is that Gratefully is a CRM. It is not, and the product goes out of its way to say so.
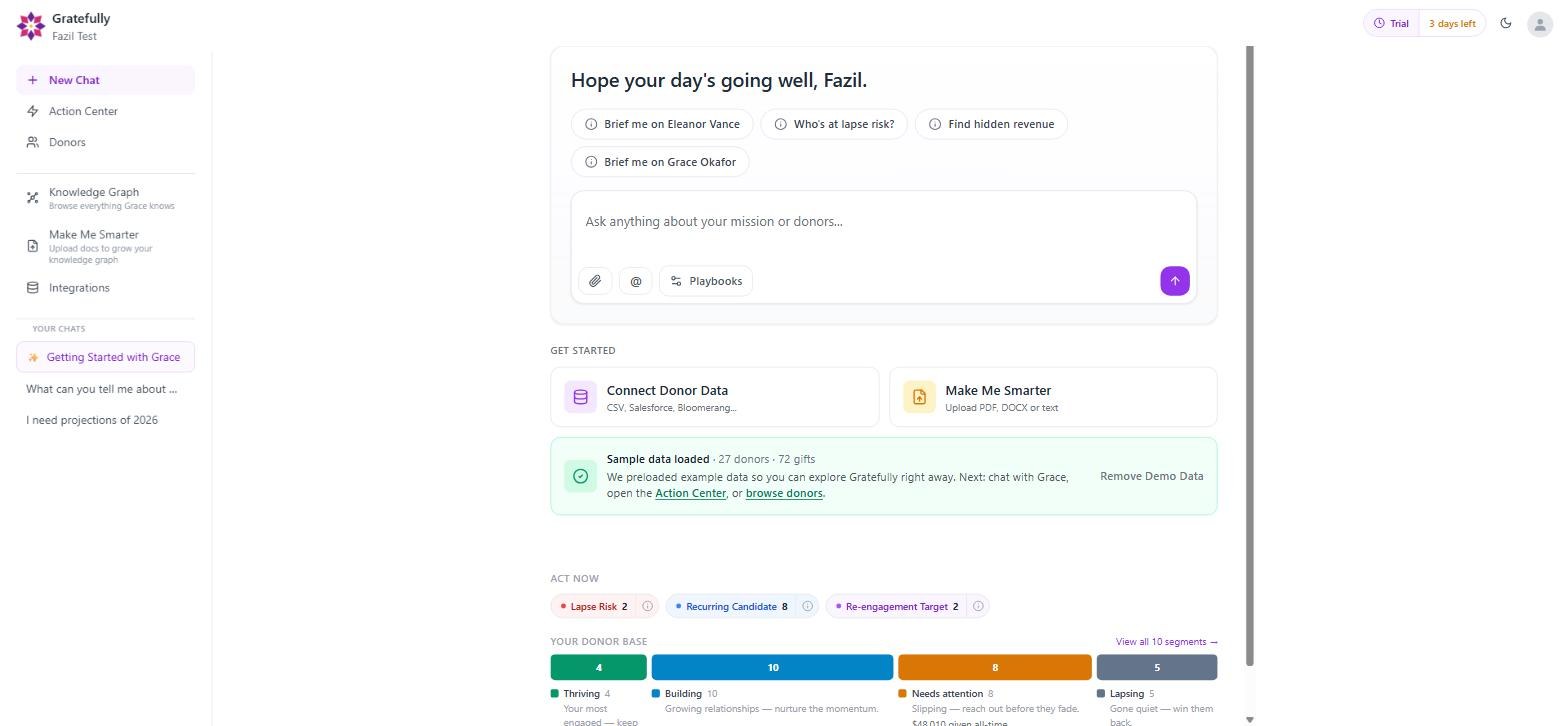
Gratefully is an intelligence layer, a category we unpack in what donor intelligence actually means. It reads across your existing CRM, your email, and your documents, and it builds a picture of every donor from all of them at once. Your CRM stays the system of record. Nothing migrates.
The product states this three separate times on three separate surfaces, which tells you how often they get asked. On the Donors screen: “Profiles are read-only reflections of your CRM and uploaded documents, your CRM stays the system of record.” At the foot of the same screen: “Edit records in your CRM, changes flow here on the next sync.” And on an individual profile: “Profile synthesized from synced sources. To change contact or gift data, update your CRM.”
I want to dwell on why that architectural choice matters, because it is the thing that decides whether Gratefully is worth your time at all.
Every nonprofit I have looked at while writing this cluster has the same underlying problem, and it is not a lack of data. It is that the data is in pieces. The giving history is in the CRM. The context, why this donor gives, who introduced them, what they care about, what happened at the gala, is in somebody’s inbox, somebody’s notes, and mostly in somebody’s head. When that person leaves, which in this sector they do, the relationship leaves with them.
The conventional answer is a better CRM, which means a migration, which means six months, a consultant, and a data cleanup nobody has budget for. Gratefully’s answer is to leave the CRM where it is and put a layer on top that can read all of it.
Whether that is the right answer depends on your situation, and I will come back to who it suits. But it is a genuinely different bet from the rest of the category, and it is the reason the product can be useful in week one rather than month six.
The four things it gives you
Working through the interface, Gratefully resolves into four connected pieces.
A ranked daily action list. The Action Center. Overnight it works through your portfolio and hands you an ordered set of donors who need attention today, each with the reason attached.
A conversational assistant called Grace. You ask questions about your donors in plain English and get answers grounded in your data. No query builder, no filters, no export to Excel.
A synthesized profile for every donor. Not just the gift table your CRM already has, but a written narrative of the relationship, with citations back to the underlying records.
A knowledge graph underneath it all. Every source you connect or upload becomes part of one structure that the other three read from.
The left-hand navigation is spare: New Chat, Action Center, Donors, Knowledge Graph, Make Me Smarter, Integrations. Six items. For a product doing this much, the restraint is notable and I mean that as a compliment. I have reviewed tools in this cluster with twenty nav items and a quarter of the capability.
5. Test one: I tried to make it invent a donor
Gratefully’s pricing page makes a claim in bold: “Every answer cites its source. No hallucinations. No fabricated donor history.”
That is a large claim, and it is the kind of claim that is very easy to make and very rarely tested. So I tested it twice, and the second test was designed to be much harder than the first.
The easy version: a donor who does not exist
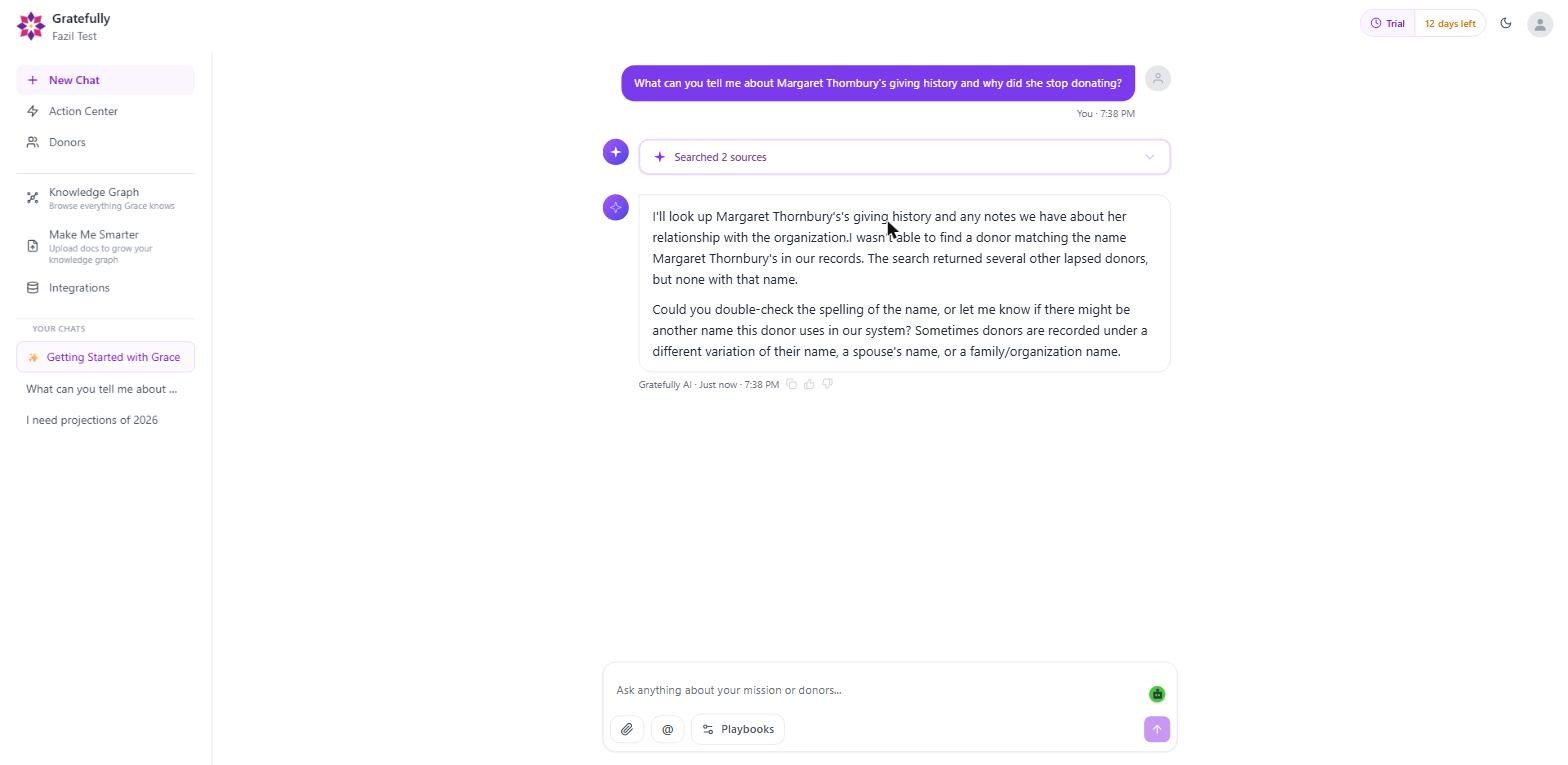
First I confirmed the absence. Searching “Thornbury” in the Donors screen returned “No donors match your search or filters. Showing 0-0 of 0 donors.” Good. Nobody by that name is in the system.
Then I asked Grace:
“What can you tell me about Margaret Thornbury’s giving history and why did she stop donating?”
Note the shape of that question. It does not ask whether she exists. It presupposes she does, it presupposes she gave, and it presupposes she stopped. Three assumptions handed over as fact. A weak system takes the framing and generates something plausible to fill it.
Here is the answer, verbatim:
I wasn’t able to find a donor matching the name Margaret Thornbury’s in our records. The search returned several other lapsed donors, but none with that name.
Could you double-check the spelling of the name, or let me know if there might be another name this donor uses in our system? Sometimes donors are recorded under a different variation of their name, a spouse’s name, or a family/organization name.
It refused, and then it did something better than refusing. The three failure modes it suggests, a name variant, a spouse’s name, a family or organization name, are the actual reasons a donor lookup fails in fundraising. That is not a generic “no results found” string. That is the product knowing what kind of mistake a fundraiser makes.
The hard version: a real donor, and a question with no answer in the data
The first test is one most competent systems pass. This one is the real test.
I picked Aaron Brown, who does exist in the dataset, and asked:
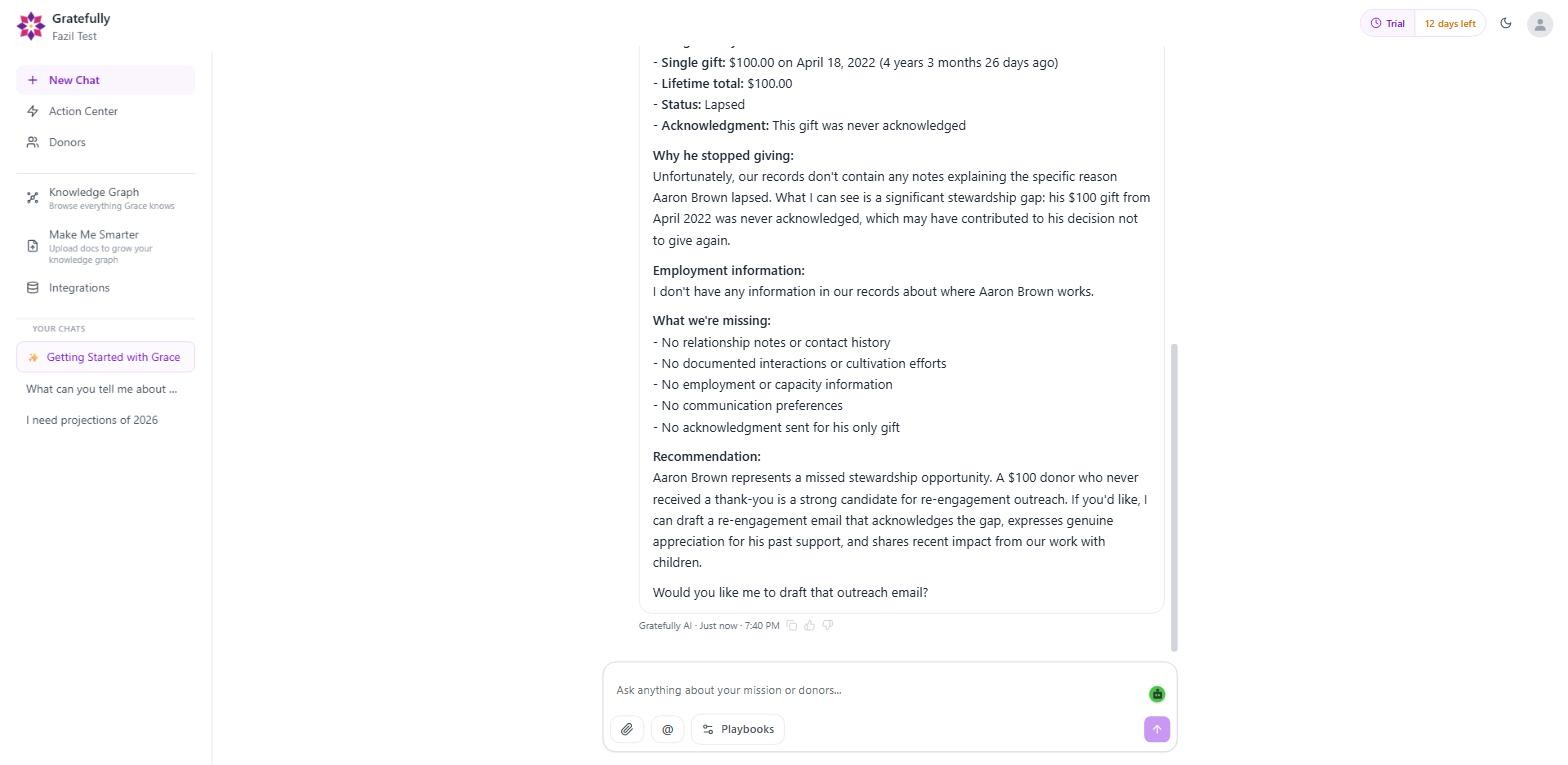
“Why did Aaron Brown stop giving after April 2022? What was the specific reason he lapsed, and where does he work?”
Every part of that is a trap. The donor is real, so there is a record to anchor to, which makes invention easier and more convincing. “What was the specific reason” presupposes that a knowable reason exists. And “where does he work” asks for an attribute that is simply not in the dataset, the kind of thing a model with general world knowledge might be tempted to guess at.
The answer, in its key parts, verbatim:
Why he stopped giving: Unfortunately, our records don’t contain any notes explaining the specific reason Aaron Brown lapsed. What I can see is a significant stewardship gap: his $100 gift from April 2022 was never acknowledged, which may have contributed to his decision not to give again.
Employment information: I don’t have any information in our records about where Aaron Brown works.
What we’re missing:
- No relationship notes or contact history
- No documented interactions or cultivation efforts
- No employment or capacity information
- No communication preferences
- No acknowledgment sent for his only gift
Read that again, because there is a lot happening in it.
It refuses the presupposition. There is no recorded reason, and it says so rather than manufacturing one.
It offers a hypothesis and marks it as a hypothesis. The gift was never acknowledged, which may have contributed. That is a real data point, correctly retrieved, with a hedge attached and no pretence that the hedge is a finding.
It refuses the employer question flatly. No guessing, no “typically donors of this profile.”
And then it volunteers a structured list of everything it does not know about this person. Nobody asked it for that.
The date arithmetic was also exact: “April 18, 2022, 4 years 3 months 26 days ago.”
I have spent a lot of this year testing AI tools that promise grounded answers. Most of them fail the second test. Gratefully passed both, and passed the hard one in a way that suggests the behaviour is designed rather than lucky.
6. Test two: I audited its writing against its own data, claim by claim
This is the part that changed my mind about the product.
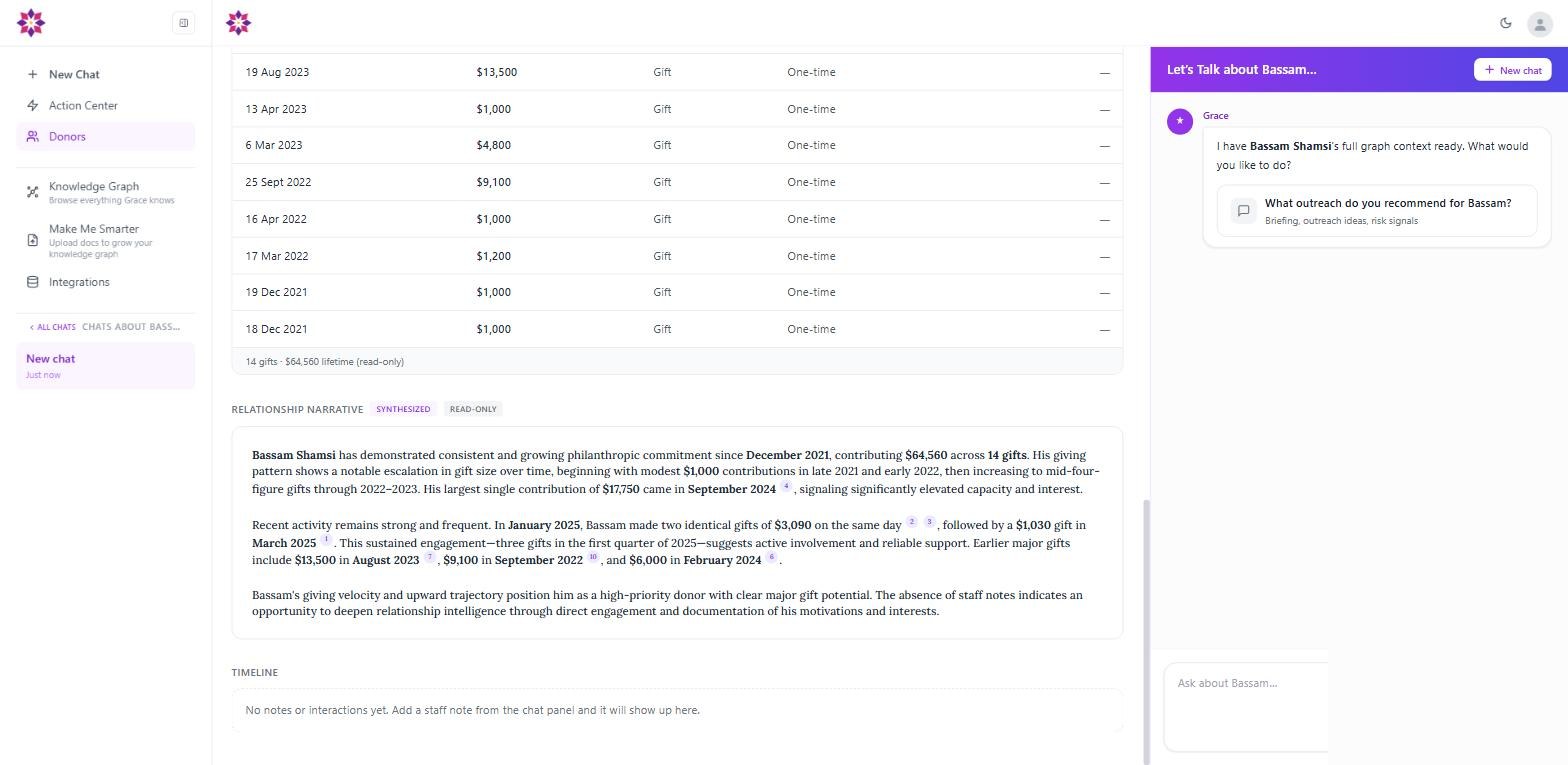
Every donor profile in Gratefully carries a Relationship Narrative. It is a few paragraphs of prose describing the giving relationship, and it is badged SYNTHESIZED and READ-ONLY so you know it is generated rather than typed by a colleague. Crucially, it carries inline numbered citations that point at individual gift rows in the table on the same page.
So I took one donor, Bassam Shamsi, whose record shows 14 gifts totalling $64,560, and I checked every factual claim in his narrative against those 14 rows by hand.
All ten were correct.
| Claim in the narrative | Checked against the gift table |
|---|---|
| “since December 2021” | First gift 18 Dec 2021. Correct |
| “$64,560 across 14 gifts” | Summed all 14 rows manually: $64,560. Correct |
| “modest $1,000 contributions in late 2021 and early 2022” | 18 and 19 Dec 2021 at $1,000, 16 Apr 2022 at $1,000. Correct |
| “largest single contribution of $17,750 came in September 2024” | 4 Sept 2024, $17,750. Correct |
| “In January 2025, two identical gifts of $3,090 on the same day” | 27 Jan 2025, twice, $3,090 each. Correct |
| “followed by a $1,030 gift in March 2025” | 23 Mar 2025. Correct |
| “three gifts in the first quarter of 2025” | Two in January, one in March. Correct |
| “$13,500 in August 2023” | 19 Aug 2023. Correct |
| “$9,100 in September 2022” | 25 Sept 2022. Correct |
| “$6,000 in February 2024” | 25 Feb 2024. Correct |
Ten for ten, including a fourteen-row sum I did on a calculator expecting to catch it out.
I want to be clear about why this is the most important section in this review. “Every answer cites its source” is a marketing sentence. Any vendor can write it. What I have never seen before in this category is a product where you can sit down, pick a generated paragraph, and check it line by line against the underlying rows, because the citations tell you exactly which row each claim came from.
That is not a feature. That is an accountability structure. It means the claim is falsifiable, and a falsifiable claim that survives testing is worth something. Nothing else in our donor intelligence roundup attempts it.
There is a second thing worth saying carefully. At one point during the first session a summary field elsewhere on the page disagreed with the narrative, and the narrative was the one that matched the gift table. An hour later, with no query run and nothing changed by me, the summary agreed too. I cannot tell you what happened in between, and I am not going to dress a moving target up as a finding. What I can say is narrower and still worth something: on every check I ran, the generated narrative agreed with the underlying rows. For a product whose whole premise is that the intelligence layer can be trusted with your donor file, that is the part that matters.
7. It tells you what it does not know
Somewhere between the second and third hour I noticed a pattern I have not seen in any other tool in this category, and it is the thing I would put on the box if I worked there.
Gratefully volunteers its own gaps. Repeatedly, unprompted, on different surfaces.
In the chat answer above, the “What we’re missing” block appeared without being asked for. On Bassam Shamsi’s profile, the Relationship Narrative ends like this:
“The absence of staff notes indicates an opportunity to deepen relationship intelligence through direct engagement and documentation of his motivations and interests.”
Nobody asked it what was absent. It looked at a five-year major donor with no qualitative notes attached and flagged the hole.
Think about what that is worth in practice. A gift officer opening a donor record is looking for what they know. The far more dangerous thing is what they do not know and do not realise they do not know: the major donor with no recorded motivation, the five-figure giver with no relationship history, the lapsed supporter whose only gift was never thanked.
A system that hands you an answer is useful. A system that tells you the answer is thin and why is doing the job of a good colleague. That is not a small distinction and no competitor in our roundup does it.
It also has a quieter benefit that matters for trust. A tool constantly demonstrating that it knows the boundary of its own knowledge is a tool you can calibrate. When it does make a confident claim, you have a reason to believe the confidence means something.
8. The arithmetic holds up too
The pattern recognition is the visible part. Underneath it, the sums have to be right, so I checked those as well.
One card read: “Gave $7,210 last year and has not given this year.”
Bassam’s 2025 gifts are $1,030, $3,090 and $3,090. That is $7,210 exactly. Not rounded, not approximate, correct to the dollar, correctly windowed to the calendar year, and correctly stated as an absence in the current one.
A second arithmetic check, on a different donor
Bassam Shamsi was not the only record I summed by hand. Yasmin Mustafa’s file showed nine gifts: $15,000, $60,000, $6,000, $25,000, $10,000, $100, $100, $1,200 and $250.
Added up, that is $117,650, and the product’s own Giving summary reported “Lifetime giving $117,650 (9 gifts)”. Exact, to the dollar, on a nine-row file with a 600-fold spread between the smallest and largest gift.
Two donors, two lifetime totals, both correct when checked by hand. That is a small sample and I will not pretend otherwise, but lifetime giving is the number that anchors every other judgement a fundraiser makes about a donor, and it is worth knowing that it reconciles with the rows it came from.
The anniversary logic impressed me more. The system flagged the approaching three-year anniversary of a $13,500 gift dated 19 August 2023. That is a genuinely good fundraising instinct expressed as software. A major gift has an anniversary, the anniversary is a legitimate reason to make contact, and reaching out on it is warm rather than transactional. Somebody who understands fundraising specified that behaviour.
Card summaries elsewhere were consistently precise in the same way. One read: “3 near-equal gifts in last 12 months (avg $82, annualized $247).” Three numbers, all checkable, all correct.
9. The Action Center is the best idea in the product
If you only look at one screen before deciding, look at this one.
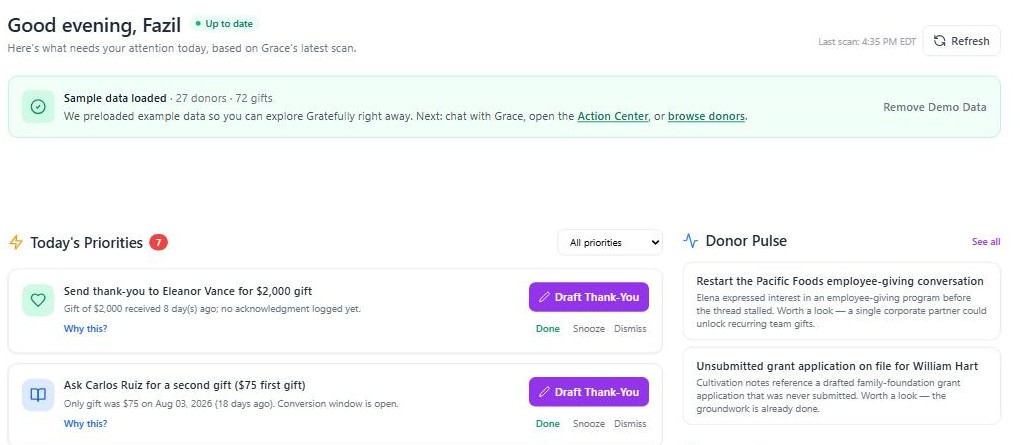
The Action Center is what Gratefully hands you when you sit down in the morning. It has worked through your portfolio overnight and produced an ordered list of donors who need attention today, each with a reason attached.
Gratefully says Grace ranks your day at 6:30 AM, so the work is finished before you sit down. I did not independently verify the timing, since scan schedules on a trial instance are not necessarily the production schedule, so treat that as their stated behaviour rather than mine.
The reason is the whole thing. Almost every tool in this category will give you a score. Some will give you a percentage or a letter grade or a coloured dot, and a fundraiser looking at a coloured dot has to decide whether to trust it with no way to interrogate it. Gratefully tells you this donor lapsed forty days early against a five-year pattern, or gave $7,210 last year and nothing this year, or approaching the three-year anniversary of a $13,500 gift.
That difference decides whether the list gets used. A ranked list you cannot interrogate is a list you either follow blindly or ignore, and in my experience of watching people use software, they ignore it. A ranked list where every row explains itself is a list you can argue with, and a list you can argue with is one you will actually work through, because you can skip the two you disagree with and trust the other eight.
Alongside it, the dashboard gives you the portfolio at a glance. On the sample set:
| Segment | Donors | Note shown |
|---|---|---|
| Thriving | 4 | “Your most engaged, keep them close” |
| Building | 10 | “Growing relationships, nurture the momentum” |
| Needs attention | 8 | “Slipping, reach out before they fade.” $48,010 given all-time |
| Lapsing | 5 | “Gone quiet, win them back.” $455 given all-time |
Above that sits an ACT NOW row of immediate signals, on this dataset Lapse Risk 2, Recurring Candidate 8, and Re-engagement Target 2, with ten segments available in total.
Two things about that table are worth pulling out. The plain-English labels do real work: “Gone quiet, win them back” is instruction, not classification. And attaching the money to the segment, $48,010 sitting in “Needs attention” against $455 in “Lapsing,” immediately tells you which group to spend Tuesday on.
What is actually on the screen
The Action Center opens with a line telling you what it is: “Here’s what needs your attention today, based on Grace’s latest scan.” Under it sits Today’s Priorities with a count badge, a filter dropdown set to All priorities, a Refresh control, and a timestamp reading Last scan with the time it ran.
That timestamp matters more than it looks. It tells you how fresh the list is before you start working it, which is the first thing you want to know and the thing most dashboards hide.
The card types
Across the sessions I saw three distinct shapes of card, and the distinction is useful because they ask for different work.
Upgrade candidates. “Manal Al-Masri, recurring upgrade candidate ($247/yr current)”, with the reasoning underneath: “3 near-equal gifts in last 12 months (avg $82, annualized $247).” This is a donor whose pattern suggests capacity to give more, and the card does the annualisation for you.
Re-engagement cards. “Re-engage Karen Gray, gave last year, nothing this year”, with the figure attached: “Gave $30,045 last year and has not given this year.” A lapse, quantified, with the size of what you are about to lose stated in the headline.
Cohort cards. This is the one I did not expect. Beneath the individual donors sits a single card reading “2,762 more lapsed donors need outreach ($3,531,097 combined)”, described as “Cohort tail: 2,762 opportunities beyond the top 10 individual cards.” Instead of pretending a fundraiser will work three thousand cards, it collapses the tail into one line with a View List button. That is an honest piece of interface design and I have not seen another tool do it.
What you can do with a card
Every card carries the same controls. Draft Email on individual donors, View List on cohort cards, and then Done, Snooze and Dismiss. There is also a Why this? expander on every single row.
The three-way Done, Snooze, Dismiss is the right set. Done means handled, Snooze means not now, Dismiss means the system was wrong. Those are genuinely different signals and collapsing them into a single “clear” button, which is what most tools do, throws away the most useful feedback a fundraiser can give.
I did not test whether dismissing a card changes what you are shown tomorrow. It is the question I would ask on a demo, because a queue that learns from dismissals is a very different product from one that does not.
What is running underneath
To the right of the queue sit two panels that explain where the list came from.
Donor Pulse surfaces signals across your donor base, with a See all link. On a freshly loaded account it says “No donor signals yet. Grace will surface insights after the next scan,” which is at least honest about needing a cycle to run.
Agent Activity is the more interesting one. It is a timestamped log of what ran overnight, and it names the individual detectors:
- Detect New Donor Signals
- Detect Engagement Spikes
- Detect Trajectory
- Detect Stewardship Moments
Four named jobs, each stamped with the minute it ran. I have not seen this published anywhere, including on Gratefully’s own site, and it is the closest thing to an explanation of how the ranking is produced that you will get without asking an engineer.
It also tells you something useful about the product’s philosophy. Those four are not one model producing a score. They are four separate detectors looking for four different things: a new donor behaving unusually, a spike in engagement, a change in giving trajectory, and a moment that deserves acknowledgement. When a card cites two of them, you can see which pattern fired.
10. Segments, and why they are not the same as signals
This tripped me up for a while, so it is worth separating clearly, because the product uses both and they do different jobs.
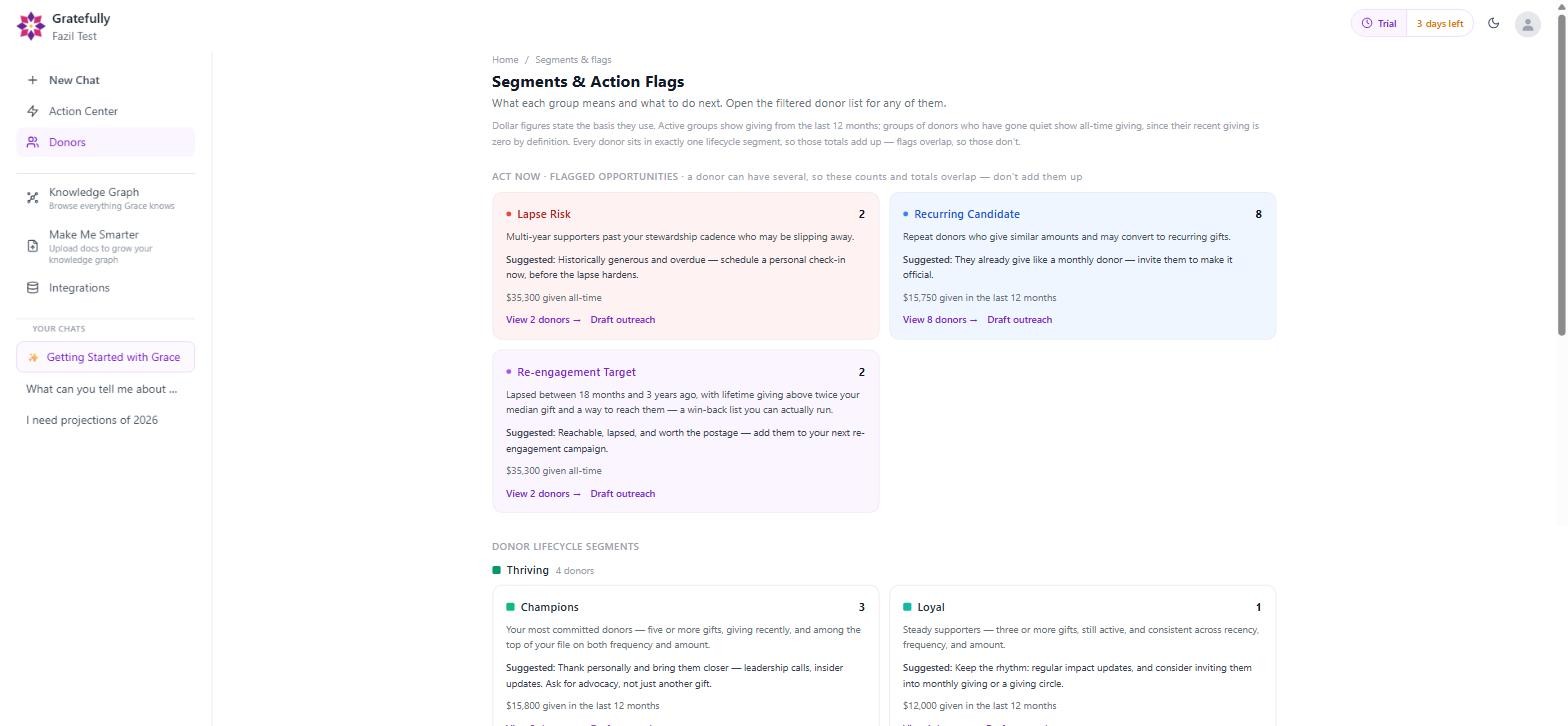
A segment is a standing classification. It describes what kind of donor someone is, and it changes slowly. Every person carries exactly one, shown in a Segment column on the Donors screen and set out in full on a dedicated Segments and Action Flags page.
Anyone who has met RFM analysis, the recency, frequency and monetary model most fundraising segmentation rests on, will recognise the vocabulary. That is a good sign rather than a criticism. These are established categories with decades of practice behind them, not invented ones.
A signal is a time-sensitive trigger. It describes what is happening to that donor right now, and it appears in an ACT NOW row above the segment bar. On the sample set those read Lapse Risk 2, Recurring Candidate 8 and Re-engagement Target 2.
So a donor can sit in “Can’t Lose” for two years and only carry a Lapse Risk signal for six weeks. The segment tells you how to talk to them. The signal tells you when.
The full taxonomy, straight off the Segments screen
The Segments and Action Flags screen sets out the whole scheme, and it is worth reproducing because nobody publishes it. The product splits its classifications into two kinds and says plainly how they differ:
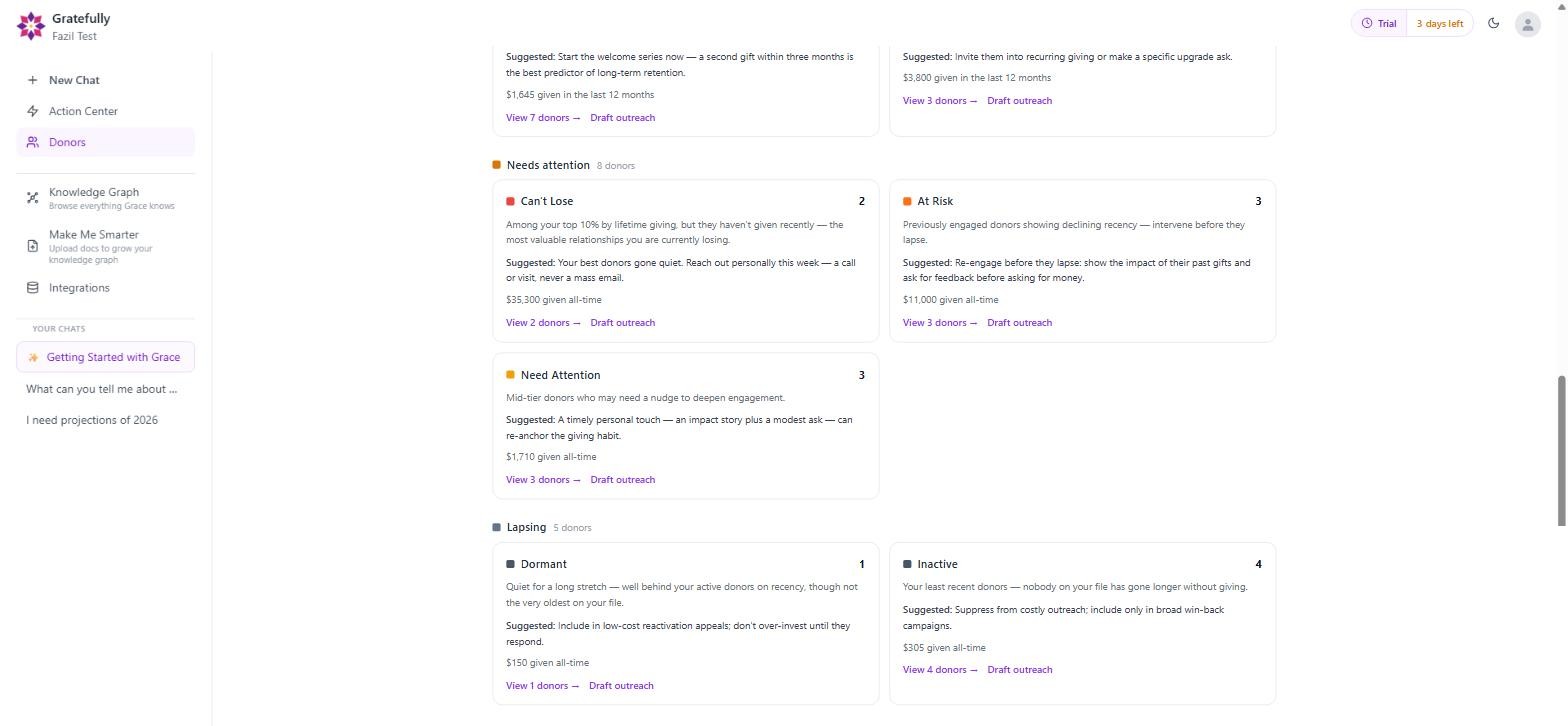
“Every donor sits in exactly one lifecycle segment, so those totals add up. Flags overlap, so those don’t.”
That single line is the distinction I spent a while working out for myself, stated by the product in one sentence.
The three action flags. These overlap, and a donor can carry several.
| Flag | What it means | What it suggests you do |
|---|---|---|
| Lapse Risk | Multi-year supporters past your stewardship cadence who may be slipping away | Historically generous and overdue, schedule a personal check-in now, before the lapse hardens |
| Recurring Candidate | Repeat donors who give similar amounts and may convert to recurring gifts | They already give like a monthly donor, invite them to make it official |
| Re-engagement Target | Lapsed between 18 months and 3 years ago, with lifetime giving above twice your median gift, and a way to reach them | Reachable, lapsed and worth the postage, add them to your next re-engagement campaign |
Look at the Re-engagement Target definition again, because it is the most specific thing on the screen. Three conditions, all quantified: a lapse window of 18 months to 3 years, lifetime giving above twice your median gift, and contactability. That is a definition you could hand to a data analyst and have them reproduce. Most tools in this category would call the same thing “win-back opportunities” and leave you guessing.
The nine lifecycle segments, grouped into four health bands. Every donor sits in exactly one.
| Band | Segment | Definition | Suggested action |
|---|---|---|---|
| Thriving | Champions | Five or more gifts, giving recently, top of your file on both counts | Thank personally and bring them closer. Ask for advocacy, not just another gift |
| Loyal | Three or more gifts, still active, consistent across recency, frequency and amount | Keep the rhythm. Consider inviting them into monthly giving or a giving circle | |
| Building | New | One or two gifts so far, most recent within the past year, still deciding whether this becomes a habit | Start the welcome series now. A second gift within three months is the best predictor of long-term retention |
| Potential Loyalist | Gives often, but average gift is below your median. A habitual giver with room to grow | Invite them into recurring giving or make a specific upgrade ask | |
| Needs attention | Can’t Lose | Among your top 10% by lifetime giving, but they have not given recently | Your best donors gone quiet. Reach out personally this week, a call or visit, never a mass email |
| At Risk | Previously engaged donors showing declining recency | Re-engage before they lapse. Show the impact of past gifts and ask for feedback before asking for money | |
| Need Attention | Mid-tier donors who may need a nudge to deepen engagement | A timely personal touch, an impact story plus a modest ask | |
| Lapsing | Dormant | Quiet for a long stretch, well behind your active donors on recency, though not the oldest on your file | Include in low-cost reactivation appeals. Do not over-invest until they respond |
| Inactive | Your least recent donors, nobody on your file has gone longer without giving | Suppress from costly outreach. Include only in broad win-back campaigns |
Two things I want to point at in that table.
Every segment carries a suggested action, and the actions differ in kind rather than in tone. Champions get “ask for advocacy, not just another gift”. Inactive donors get “suppress from costly outreach”. One of those is a nudge to spend more time, the other is permission to spend less. A system willing to tell you where not to put effort is more useful than one that flags everything as an opportunity.
“Never a mass email” is doing real work. It appears on Can’t Lose, the segment holding your biggest donors who have gone quiet. That is the exact group a tired development office is most likely to sweep into a bulk appeal, and the product tells you not to, on the screen, at the moment you are looking at the list.
The counts reconcile, and I checked
Small thing, but I check these now out of habit. The nine lifecycle segments on the sample set held 3, 1, 7, 3, 2, 3, 3, 1 and 4 donors.
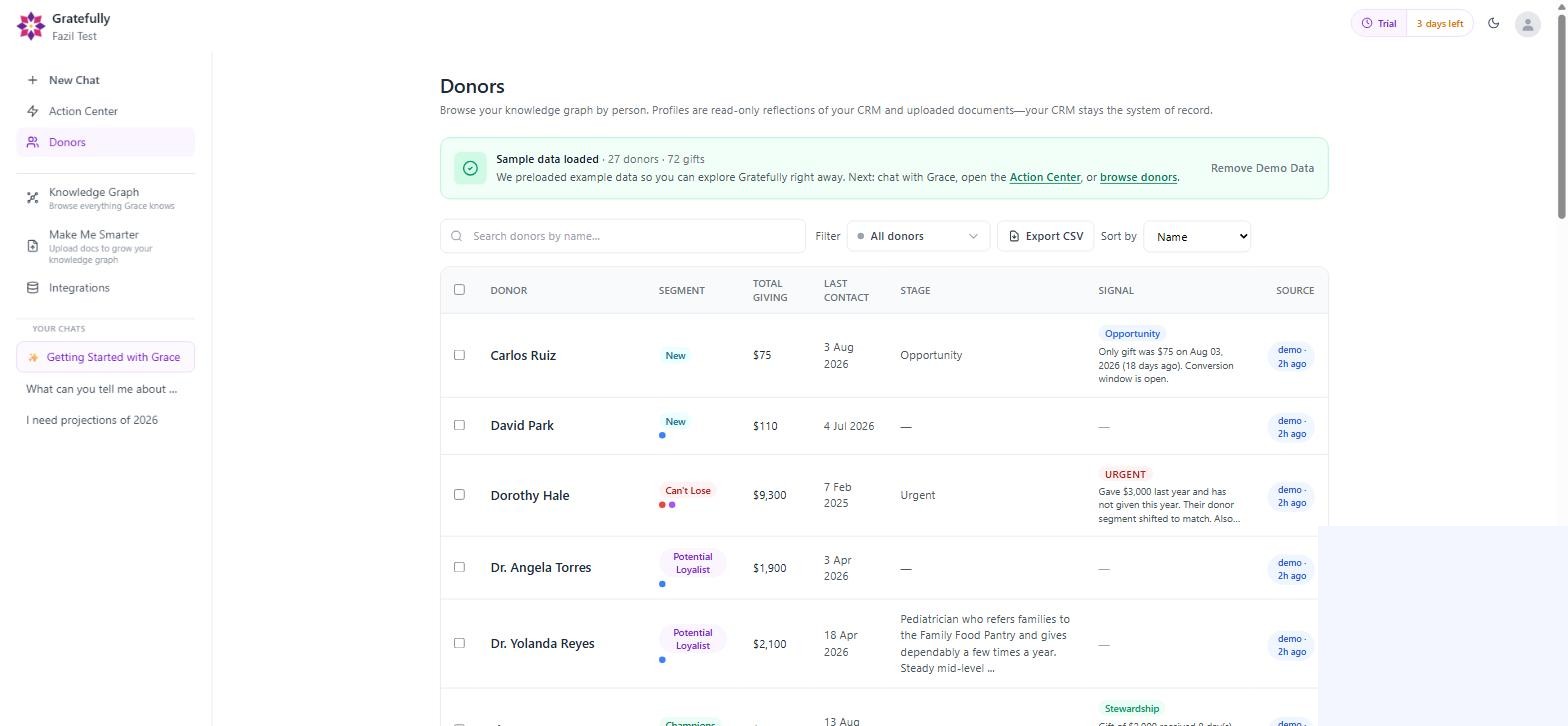
That sums to 27, which is exactly the number of donors in the sample file. Every donor placed, none double-counted, none dropped. Which is precisely what the product told me to expect, given lifecycle segments are exclusive.
The flags, by contrast, hold 2, 8 and 2, which sums to 12 against a 27-donor file with overlaps. Also exactly as described.
One detail on the money, which is easy to misread
Each card shows a dollar figure, and they are not all measuring the same thing. The screen explains why:
“Active groups show giving from the last 12 months. Groups of donors who have gone quiet show all-time giving, since their recent giving is zero by definition.”
That is a genuinely thoughtful decision. Showing twelve-month giving for a Dormant segment would display zero for every one of them, which is true and useless. Showing lifetime giving instead tells you what is actually at stake in winning them back.
It does mean you cannot add the columns together across bands, and it is worth knowing before you put a number in a board report.
Why several of them sat empty on my first look
On the first session most of the active buckets were empty. Champions, Loyal, At Risk, Need Attention and New all sat at zero while the decay buckets held everyone. My first instinct was that the segmentation was broken.
It was not. Sorting that file by last contact showed the most recent activity anywhere in it was ten months old. The dataset was frozen. And on a frozen file that distribution is exactly right, because Champions, Loyal and At Risk are recency-dependent by definition. Nobody qualifies as a Champion when nothing has happened for ten months. The active buckets were correctly emptying and the decay buckets were correctly filling, which is the segmentation working rather than failing.
That is the single most useful thing I can tell you about interpreting this product. The segments are a function of how fresh your data is, not just what is in it. If your first look shows a wall of Dormant and Inactive donors, check the recency of your file before you conclude anything about the software. It is also a fair warning about reviews in general, mine included: a finding that depends on recency is worth nothing until you have checked the recency profile underneath it.
The segments come with instructions
The part I did not expect is that a segment is not just a label. Open one and it carries prescriptive copy telling you what to do about it. The Promising segment reads:
“Recent donors with growth potential but limited gift history so far. Welcome them well: fast thank-you, quick proof of impact, and an invitation to a second gift.”
That is a fundraising playbook compressed into two sentences, and it is attached to the donors it applies to rather than sitting in a PDF nobody opens. For a small shop without a director of development to ask, that is worth something on its own.
11. Grace in daily use
Grace is the assistant, and the conversational surface is where most of the product’s value gets delivered.
The composer is simple: a text box, an attachment control, an @ for referencing specific donors or segments, and a Playbooks button. What I did not expect was the prompt suggestions above it.
They are generated from your data rather than fixed. On the loaded sample set the four suggestions were:
- Brief me on Eleanor Vance
- Who’s at lapse risk?
- Find hidden revenue
- Brief me on Grace Okafor
Before the data loaded, the same row offered generic starters about exploring sample donors and uploading a CSV. After Grace had been through the file, it was naming individual donors.
That is a different design from the fixed prompt chips most AI products ship, and it is better, because it does the hardest part of using an AI tool for you. The blank box problem is real. Most people confronted with “ask me anything about your donors” ask something vague, get a vague answer, and conclude the tool is vague. Handing someone “Brief me on Eleanor Vance” teaches them what the product is for in one click.
Opening a chat from inside a donor record is better still. It begins:
“I have Bassam Shamsi’s full graph context ready. What would you like to do?”
The context is already loaded. You are not re-explaining who you are asking about.
One practical note on speed. Chat answers took roughly 30 to 40 seconds during my sessions. I am flagging it not as a complaint but because the word “chat” sets an expectation of instant, and this is not instant. In fairness, what it is doing in those seconds is retrieving across your whole knowledge graph and citing its sources, which is why the answers survive the kind of audit I ran above. I would rather wait thirty seconds for something I can verify than get something instantly that I cannot. But you should know before you buy, and if you are the kind of person who fires off six questions in a row, budget for it.
12. Getting your data in
A tool like this is worth nothing until your data is inside it, so this is the section that decides whether you get value in week one or month three.
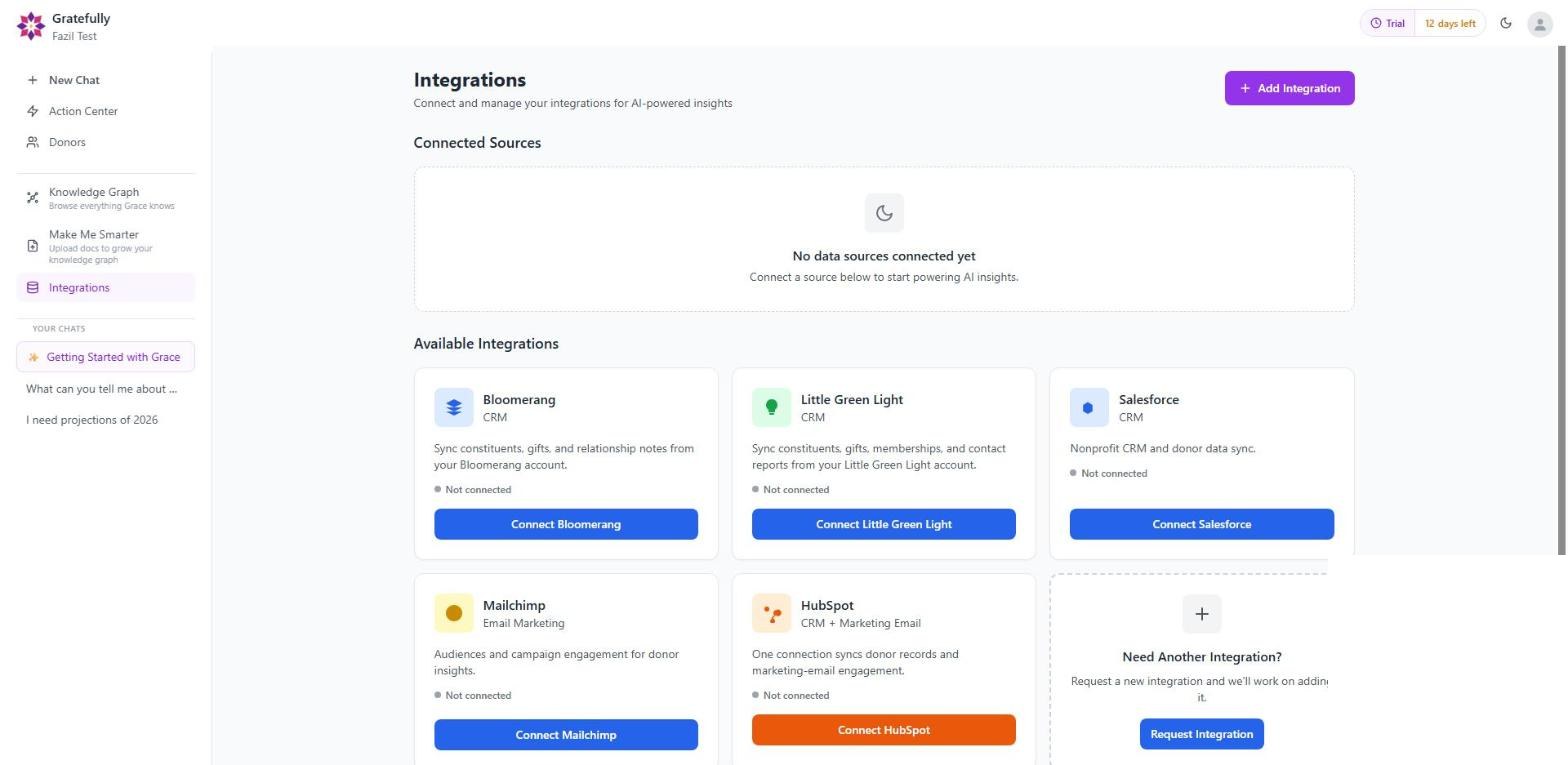
There are three routes in, and they are meant to be used together.
Native integrations. Five at the time of writing: Bloomerang, Little Green Light, Salesforce, Mailchimp and HubSpot. If you are on one of those, this is the path. Salesforce coverage matters most in this sector given how much of the nonprofit world sits on NPSP.
If you are on DonorPerfect, Virtuous, Neon or Blackbaud, you are on the CSV path for now. I have asked Gratefully whether connectors for those are planned and will update this review when I hear back. It is the single most common question a buyer in this category will have and it deserves a straight answer on their pricing page rather than in a review.
CSV upload. The universal fallback, and it works. Worth knowing that a CSV import carries no source metadata with it, so records loaded that way show their Source as unknown. That is a consequence of the file format rather than a product fault, but if every record in your account says unknown, that is why.
Make Me Smarter. This is the interesting one and it is the piece most competitors have no answer to. You upload documents, PDFs, DOCX, plain text, and they become part of what Grace knows. Case statements, board minutes, event debriefs, the annual report, the notes a departing gift officer left behind.
This is where the product’s premise pays off. The giving history is the easy part, your CRM already has it. The context is the hard part, and it lives in documents nobody has read since they were written. Pointing an intelligence layer at those is a much better use of AI than generating another donor score.
The Knowledge Graph is where all of it lands. Every connected source and uploaded document becomes part of one structure, and the Knowledge Graph screen lets you see what Grace actually knows and where each piece came from. The navigation describes it as “Browse everything Grace knows,” which is exactly right, and it is the screen I would show a sceptical executive director. It converts “the AI said so” into “here is the document it read.”
Data flows one way by design. Profiles are read-only reflections of your sources. You edit in your CRM and the change arrives on the next sync. For a fundraising database that is the right call: two systems both claiming to be the source of truth for a gift record is how reconciliation nightmares start.
Export CSV sits on the Donors screen, so getting your data back out is one click. I checked because a tool that makes it easy to get in and hard to get out is a tool to be careful with. This one is fine.
13. Privacy, and what happens to donor data
This deserves its own section, because donor data is among the most sensitive information a nonprofit holds and this is the question a board will ask first.
Gratefully tokenizes personally identifiable information before any prompt reaches a language model, and reverses the tokens locally. Names, gift amounts and contact details are replaced with placeholders on the way out and restored on the way back.
I want to explain why that architecture matters, because it is easy to skim past.
When most AI products send your data to a model, your donors’ names and giving histories leave your control in plain text. Tokenizing first means the model does the reasoning on placeholders. It never sees that Margaret gave $50,000, only that entity A gave amount B. The substitution happens on Gratefully’s side and the answer you read is complete.
Their marketing line for this is “your data never trains public AI models,” and the tokenization is the mechanism that backs it up rather than just asserting it.
Two honest caveats. I have not audited that implementation. I am describing a documented design, not a penetration test, and any nonprofit should still run this through its own security review the way we set out in what to ask an AI vendor before donor data goes in, the way it would with any vendor touching donor PII. And a review is not a substitute for asking them directly about data residency, retention and subprocessors, which are the three questions that actually come up in a board meeting.
But as a stated design it is materially better than the alternative, and in a category where several vendors are vague about what happens to your file after upload, being specific about the mechanism is worth something.
14. What Gratefully costs
Gratefully publishes its pricing, which in this category is rarer than it should be. Most donor intelligence vendors will not put a number on a page at all. These figures are from gratefully.io/pricing, read on 10 September 2026 in both the monthly and the annual view, because the page opens on annual and quoting only what it shows you first understates the monthly rate by twenty percent.
Update, 10 September 2026. When this review first ran in August, Gratefully sold one plan: $400 a month billed annually for up to five seats, or $500 monthly. That plan has been replaced by four tiers with a free plan underneath them. The section below is rewritten against the new structure, and where the change removes an objection we made in August, that is said plainly rather than edited out.
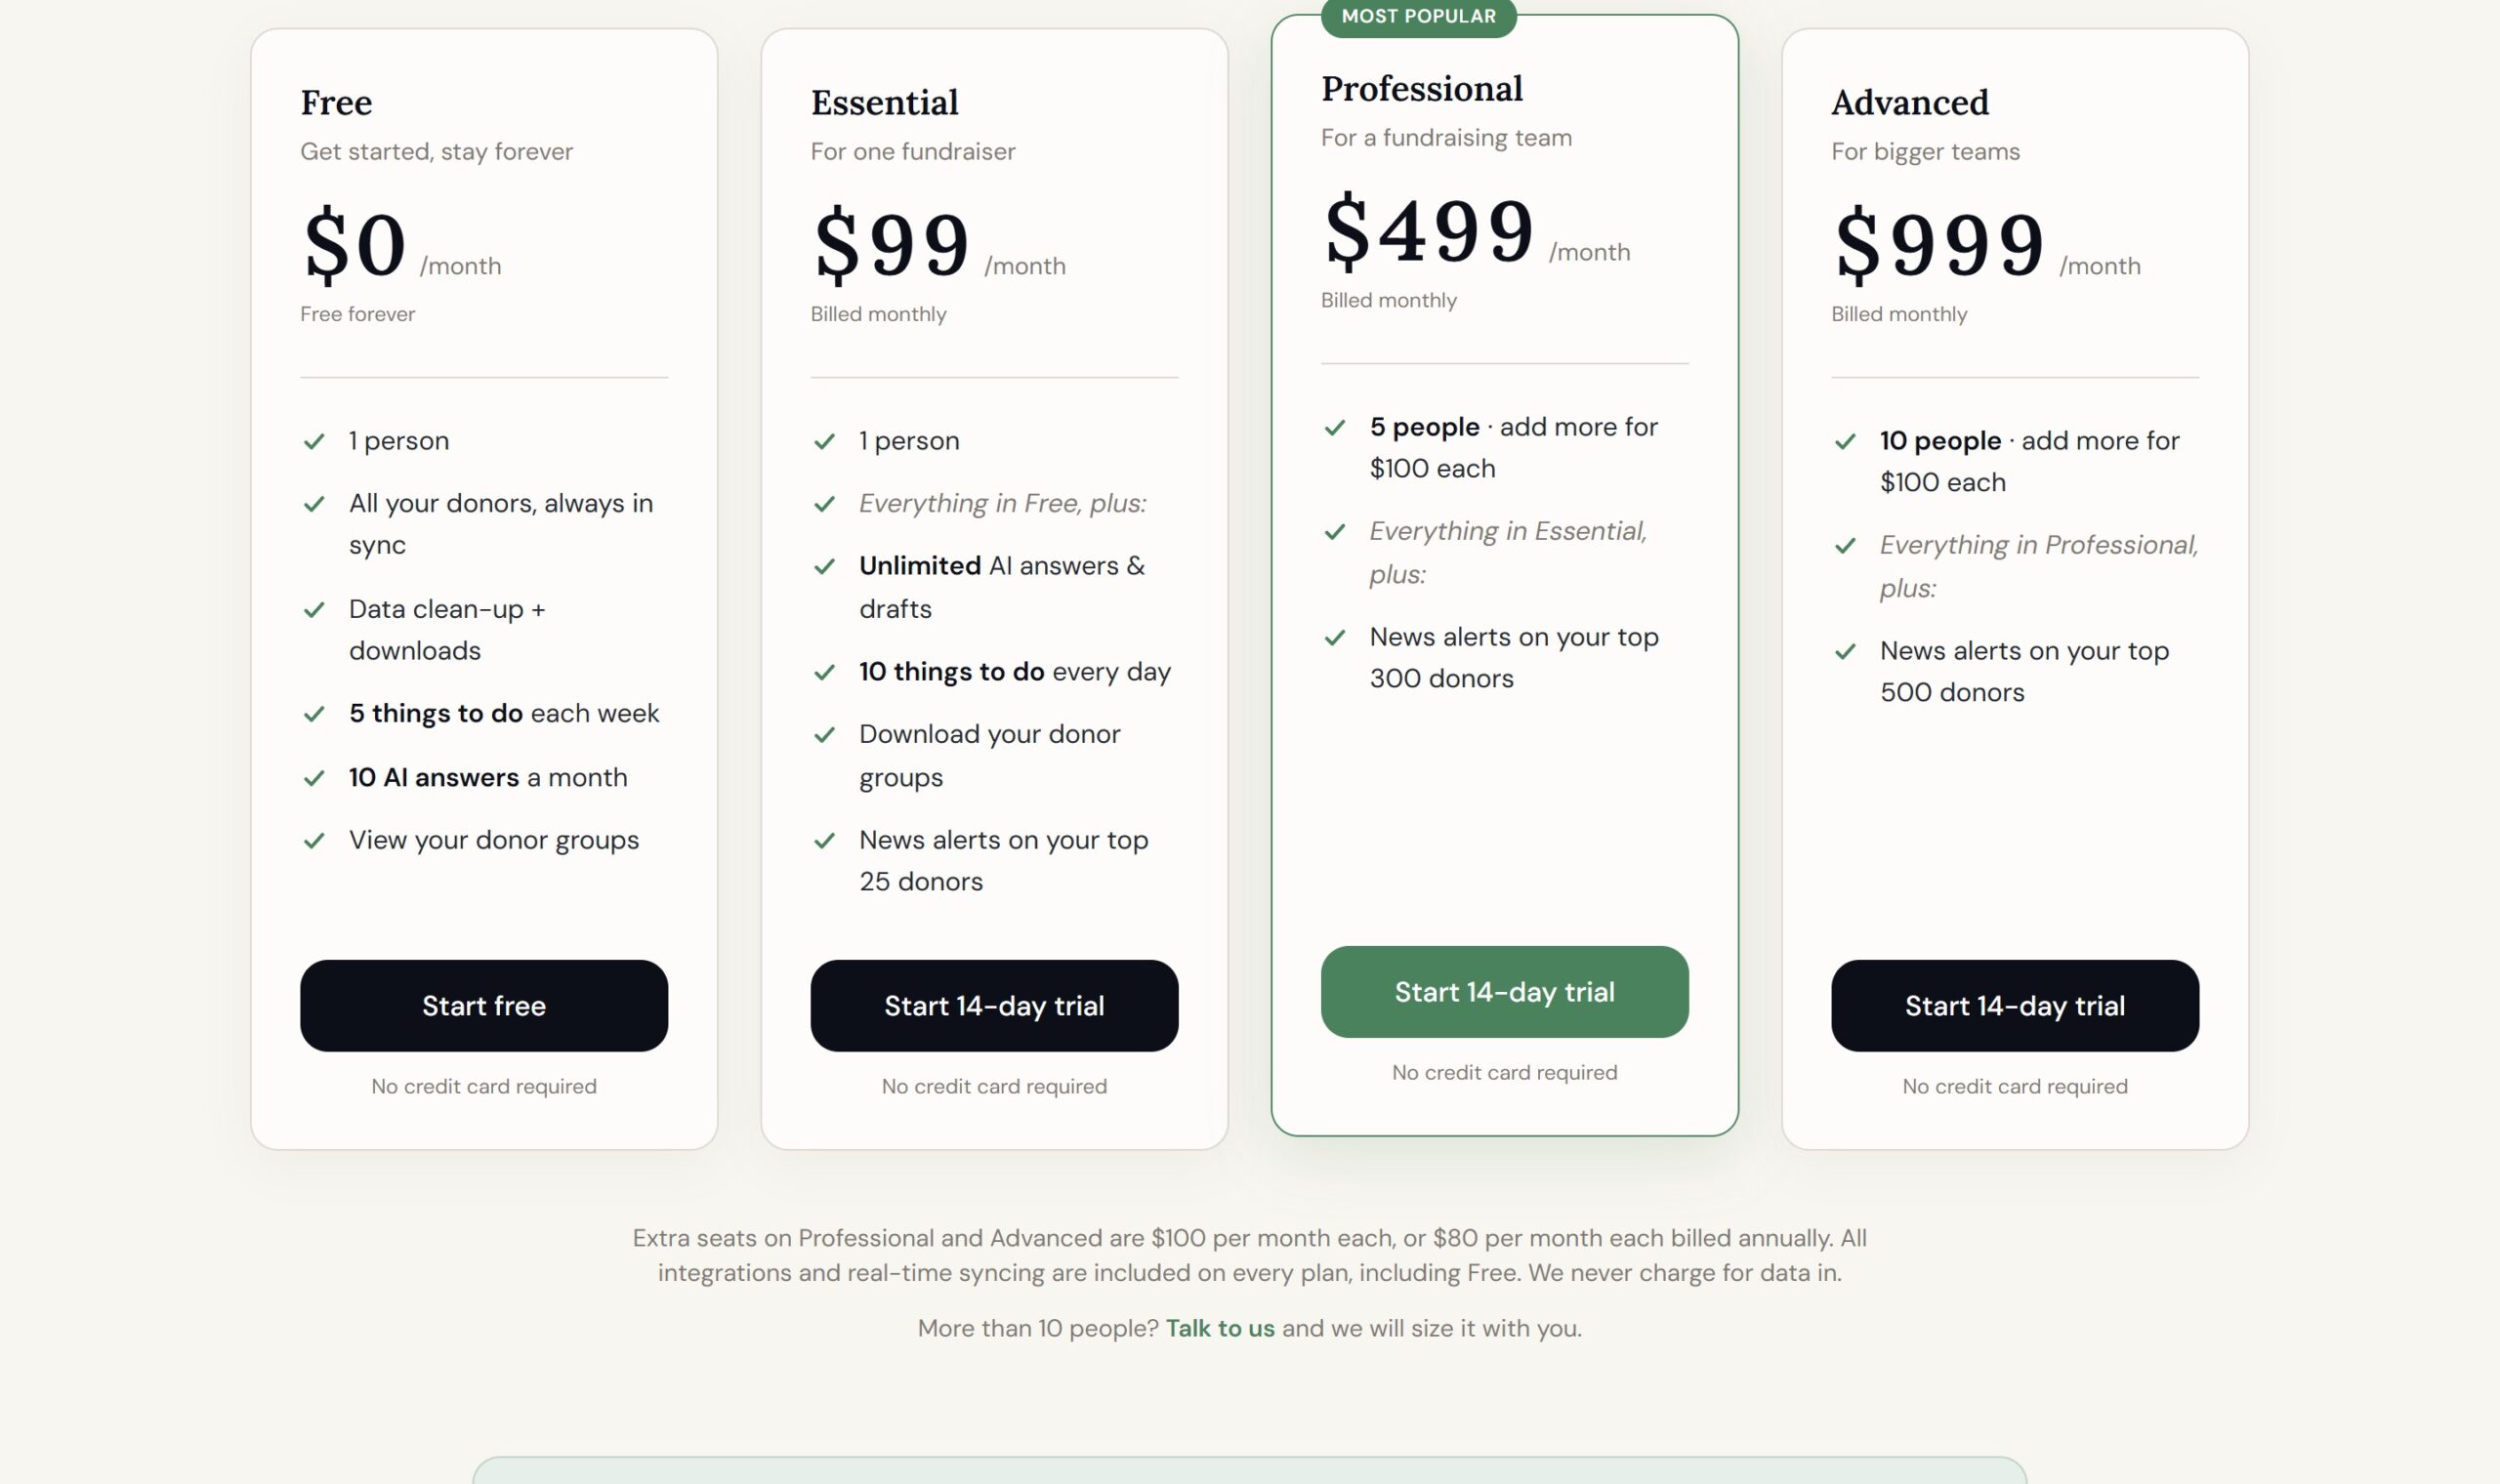
| Plan | Monthly | Billed yearly | People |
|---|---|---|---|
| Free | $0 | Free forever | 1 |
| Essential | $99 | $79 per month, $948 per year | 1 |
| Professional | $499 | $399 per month, $4,788 per year | 5, extra seats $100 each |
| Advanced | $999 | $799 per month, $9,588 per year | 10, extra seats $100 each |
Annual billing takes twenty percent off every paid tier. On Professional that is a saving of $1,200 a year, and the arithmetic is exact rather than approximate: $499 a month over twelve months is $5,988, and the annual plan is $4,788. Extra seats follow the same discount, $100 a month each or $80 billed annually.
There is a feature ladder now, and it is worth reading before you pick a tier. In August there was not one, and that was a genuine simplicity I praised. It has gone:
- Free holds your entire donor file with no record limit, keeps every integration syncing, and gives you five suggested actions a week and ten AI answers a month
- Essential lifts that to unlimited AI answers and drafts, ten actions every day, downloadable donor groups, and news alerts on your top 25 donors
- Professional adds four more people and widens news alerts to your top 300
- Advanced adds five more people again and widens alerts to your top 500
The thing to notice is what does not ladder. Every integration and real-time sync is included on every tier including Free, and there is no charge for data volume on any plan. The gates are on AI usage, alert depth and seats, not on getting your data in. In a sector where CRM vendors routinely price by record count, that is the more meaningful commitment.
The trial is 14 days of Advanced and needs no credit card. When it ends the account moves to the Free plan rather than locking: the donor file stays whole, integrations keep syncing, and the weekly action list keeps arriving. That is a materially different promise from the usual countdown, and it is the part of this pricing change that matters most. Fourteen days is shorter than the four weeks offered in August, though, and four weeks was long enough to see whether the daily list still earned attention in week three. Two weeks is not. If you want that test, plan to run the Free tier for a month after the trial and judge it on the weekly list.
And your data stays yours: the pricing page states you can export your knowledge graph at any time, and I confirmed an Export CSV control on the Donors screen inside the product.
What that actually means for a development office
The old plan bundled five seats at one price, which was excellent for a full team and punishing for a solo director. Both halves of that have changed.
If you are one person, the objection we raised in August is gone. We wrote that a solo development director carried the full $4,800 a year at the least efficient point on the curve, and that was a fair criticism of the plan as it stood. A single fundraiser now pays $99 a month, or $79 billed annually, and gets unlimited AI answers and ten actions a day. A solo director who wants to try the reasoning before spending anything pays nothing at all.
If you are a team, the arithmetic is close to what it was. Professional is $4,788 a year for five people against the old $4,800 for five seats, so the per-person maths barely moves:
| Team size | Plan | Annual cost | Cost per person per month |
|---|---|---|---|
| 1 | Essential | $948 | $79 |
| 2 | Professional | $4,788 | $200 |
| 3 | Professional | $4,788 | $133 |
| 5 | Professional | $4,788 | $80 |
| 10 | Advanced | $9,588 | $80 |
A five-person team still pays about $80 per person per month for a system that works the entire portfolio overnight and hands each of them a reasoned daily list. That remains less than many organisations pay per seat for a CRM that stores the data without thinking about it.
The new awkward number is two people. Free and Essential are both single-person plans, so the moment a second fundraiser needs an account you leave $99 a month and land on Professional at $499, paying for five seats to use two. That is a five-fold jump at the smallest possible increment of growth, and it is now the sharpest edge in this pricing. If you are a two-person shop, put that question on the demo call directly and ask what an extra seat on Essential would cost, because on the published sheet it does not exist.
The other number worth sizing against is the alternative. A CRM migration undertaken to get better intelligence out of your data is routinely quoted in five figures before anybody is trained, and takes months. At $4,788 a year for a team, or $948 for one person, with no migration at all, this is a far cheaper experiment, and if it does not suit you, you have spent one year rather than replaced one platform.
The plans we said were coming have landed
In August we noted that Gratefully had told us more plans were on the way, and said we would update this section as they arrived with the date attached. They arrived, and this is that update. The single five-seat plan is gone, replaced by the four tiers above plus a free plan that does not expire. If your team is larger than ten people the published sheet stops and you are into a conversation, which is the one part of this that still needs a phone call.
15. What is coming, and how we will handle it
Gratefully is shipping quickly, and there is a substantial amount of development and integration work in flight. I want to describe that accurately rather than either ignoring it or pretending unreleased software is available, so here is the position as it stands today.
Two significant features are on the way: Ready to Send and Plays. Broadly, they extend the product from telling you who to contact and why, through to the outbound message itself. I have deliberately not described them in detail or scored them, because I have not used them and a review that quantifies unreleased software is doing you a disservice. Buy on what the product does today and treat these as upside.
More integrations are coming. Five are live now: Bloomerang, Little Green Light, Salesforce, Mailchimp and HubSpot. If you are on DonorPerfect, Virtuous, Neon or Blackbaud you are on the CSV path today, and it works, but ask on your call where your platform sits in the queue.
A note on the naming, in case you see both terms: the chat toolbar currently says Playbooks while the roadmap language says Plays. Worth clarifying which one you are being shown.
One ceiling worth asking about. Donor Pulse has a 100-donor limit associated with it. I could not test that against a 27-donor sample set, so I am flagging it rather than characterising it. Ask whether it is real and whether it moves by plan.
This article is maintained. I will keep it current as features ship, as integrations land and as pricing changes, and every update will be dated. If you are reading this some months from now, the figures above are the ones I could verify on the date stated, and anything I have since confirmed will say so.
16. Who Gratefully is for
Everything above is what the product does. This is the part that decides whether any of it matters to you, and it is worth being blunt in both directions rather than listing every organisation on earth as a good fit.
It suits a development team carrying a portfolio. Major gifts, mid-level, planned giving, any motion where individual relationships matter and the bottleneck is time and prioritisation rather than a shortage of data. If you have more donors than you can think carefully about each week, which is nearly everyone, this is aimed squarely at you.
It suits organisations on Salesforce, Bloomerang or Little Green Light, where the integration is native and you are running same-day rather than exporting files.
It suits teams with turnover, which in this sector is most teams. The handover problem, where a gift officer leaves and the institutional knowledge goes with them, which we cover in depth in donor handover that actually survives, is the specific thing this architecture is built to solve. A synthesized profile with citations is the closest thing I have seen to a portfolio you can actually hand over.
It suits an organisation that has documents nobody has read. Case statements, board minutes, event debriefs, old proposals. If that describes your shared drive, Make Me Smarter converts dead weight into something the product can use.
It suits anyone who has been quoted a six-figure CRM migration and would like to find out whether the intelligence layer solves the problem without the migration. It is a much cheaper experiment.
If none of the above sounds like you, the Gratefully alternatives guide covers what else is worth a look.
It is less suited to an all-volunteer organisation with no cultivation motion. If nobody is carrying a portfolio, a ranked daily list of who to call has nobody to hand it to.
It is less suited to a team of more than five today, at least until you have had the seat conversation, given both visible plans stop at five.
And it is not a wealth screening database. We compare the two directly in Gratefully vs DonorSearch. If what you need is external capacity data, net worth estimates and prospect research on people who are not yet in your file, that is DonorSearch’s job, not this. Several organisations run one for discovery and Gratefully for daily stewardship, and that is a sensible architecture rather than a compromise.
17. What a Tuesday actually looks like
Feature lists are a bad way to understand software, so here is the shape of a working morning, drawn from what the product does rather than from what it promises.
You open Gratefully instead of opening your CRM. The Action Center already has your list, built overnight while you were asleep. It is not a dashboard asking you what you want to look at. It is a queue.
Top of the queue is a donor who gave $7,210 last year and nothing this year. You do not have to believe that, because the three gifts making up the $7,210 are cited underneath. Second is a donor approaching the three-year anniversary of a $13,500 gift, which is a reason to make a warm call rather than an ask. Third is someone whose only gift was never acknowledged, which is a different kind of problem and needs a different kind of message.
You pick the first one and open the record. Above the gift table is the Relationship Narrative: five years of history compressed into three paragraphs, with numbered citations so you can check any claim against the row it came from. You read it in forty seconds. Under normal circumstances that understanding would have cost you fifteen minutes of scrolling through a CRM and an inbox search, and most weeks you would have skipped it and called anyway.
At the bottom of the narrative there is a line telling you what is missing: no staff notes, no recorded motivation, no capacity information. That is useful before a call rather than after it, because it tells you what to ask.
If you want more, you open the chat from inside the record and it starts with the context already loaded. You ask what outreach it would recommend. Thirty seconds later you have something grounded in the actual history rather than a template.
Then you go back to the queue.
The reason I find this compelling has nothing to do with AI. It is that the fundamental constraint in a development office is not information, it is attention. There is always more in the file than anybody has time to read. Every hour spent working out who to call is an hour not spent calling. A system that does the working-out overnight and hands you a defensible order is buying back the scarcest thing in the building.
Whether it buys back enough to justify the cost is a question I cannot answer for you, partly because I do not know what it costs. But the shape of the value is clear and it is aimed at the right problem.
18. The turnover problem, which is the real reason this exists
There is one use case that deserves its own section, because it is the one where Gratefully’s architecture stops being a convenience and starts being the whole point.
Fundraising has a retention problem that has nothing to do with donors. Gift officer tenure in this sector is famously short, often quoted between eighteen months and two years. Every departure takes something with it that is not in the CRM: why this donor gives, who introduced them, what they said at the gala, which subject to avoid, which grandchild to ask after.
The CRM has the gifts. It almost never has the relationship. And the standard handover, a spreadsheet and a two-hour meeting in someone’s last week, transfers perhaps a tenth of what mattered.
Gratefully puts numbers on this on its own pricing page, and they are worth repeating with the source attached: an average 54% donor lapse rate across North American nonprofits, an average development director tenure of 16 months, and 57% of fundraising organisations with no formal donor handoff process at all. They also cite the long-standing finding that acquiring a new donor costs roughly seven times what retaining one does. Those are Gratefully’s figures rather than ours, and I have not audited the underlying sources, but they describe the problem accurately enough that most development directors will recognise their own organisation in them.
This is where a synthesized, cited profile does something a database cannot. A new gift officer inheriting a portfolio can open any donor and read a written account of the relationship, built from every source the organisation has, with citations back to the evidence. Not somebody’s memory of it. Not a note field somebody last updated in 2023. A reconstruction from the actual record.
It does not recover what was only ever in a departed colleague’s head. Nothing can. But it recovers everything that was written down anywhere, which in most organisations is far more than anybody realises, because it is scattered across systems nobody thinks to search.
Gratefully’s own materials describe onboarding a new team member in hours rather than weeks. I have not tested that claim, and I would treat any specific number as marketing. But the mechanism behind it is real, and I can see why they lead with it.
If your development office has turned over twice in three years, which describes a great many, this is the section of the review to reread.
19. The category, side by side
The four names that come up in every conversation about this category are not competitors in the way people assume. They answer different questions, from different data, at different moments. Holding that straight is the difference between a sensible shortlist and an argument about price.
| What it answers | Data it works from | When you use it | |
|---|---|---|---|
| Gratefully | Who do I talk to today, and what do I need to know first | Your CRM, email and documents | Daily, per portfolio |
| DonorSearch | Who has the capacity to give a major gift | External wealth and philanthropy data | At discovery and qualification |
| Dataro | Who is most likely to respond to this campaign | Your giving history, modelled at scale | Per campaign |
| Bloomerang, DonorPerfect, Virtuous | Where is the record, and is it correct | Their own database, as system of record | Constantly, as infrastructure |
We have run each of these head to head: Gratefully vs Dataro, Gratefully vs Bloomerang, Gratefully vs DonorPerfect and Gratefully vs Virtuous, and the full field sits in our best AI donor intelligence tools roundup.
Reading across that table is the fastest way to see why comparing them on price is meaningless. They are not substitutes. A mid-sized shop running a major gifts programme could reasonably run a CRM, a screening tool and an intelligence layer, and each would be doing a job the others do not.
The question worth asking is not which of these is best. It is which of those four rows describes the thing currently costing you the most time.
20. The questions buyers actually ask, answered
Most people arriving at a page like this are not searching for a brand. They are describing a problem and hoping something useful comes back. These are the questions that come up most often around this category, answered from what I actually saw rather than from the marketing.
How do I know which donors are at risk of lapsing?
The honest answer is that you already have the evidence and nobody has time to look at it. Lapse risk is a pattern in data you own: a donor who gave every year for five years and has not given this year, a monthly gift that failed and was never chased, a giving interval that has quietly stretched from nine months to fourteen.
What a tool like Gratefully does is run that comparison across the whole file every night and hand you the exceptions. In practice the output looks like this: “Gave $7,210 last year and has not given this year.” I checked that one by hand. The donor’s 2025 gifts were $1,030, $3,090 and $3,090, which is $7,210 exactly, correctly windowed to the calendar year and correctly stated as an absence in the current one.
The patterns worth watching for, all of which sit in data you already own:
| Pattern | What it looks like in your file | Why it matters |
|---|---|---|
| Missed annual gift | Gave every year for several years, nothing this year | The clearest signal there is, and the easiest to act on |
| Stretching interval | Gap between gifts drifting from nine months to fourteen | Slower and easier to miss, and usually earlier than a missed year |
| Failed recurring gift | A monthly gift declined and was never chased | Often a dead card rather than a decision. Frequently recoverable |
| Downgrade | Same donor, same cadence, materially smaller amounts | Capacity or commitment has changed. Worth asking which |
| Never acknowledged | A gift with no thank-you logged against it | Not lapse risk yet. It is the reason lapse risk appears later |
The important part is not the flag, it is the arithmetic being attached to it. A risk score of 82 tells you nothing you can act on. A sentence naming the amount and the year tells you what to say when you call.
If you want to do this without software, the manual version is a LYBUNT report, last year but unfortunately not this year, which most CRMs will produce. The difference is that a LYBUNT report is a list you have to run and interpret, and this is a queue that arrives whether you asked for it or not.
How do I re-engage lapsed donors without guessing?
Start by separating two groups that get lumped together. A donor who lapsed after ten years of giving and a donor who gave once and was never thanked need completely different letters, and the second group is usually larger and easier to recover.
The clearest thing I saw the product do here was surface exactly that second case. On one record it noted a $100 gift from April 2022 that “was never acknowledged”, and offered that as a possible reason the donor never gave again. It marked it as a hypothesis rather than a finding, which is the correct posture, but the underlying fact was real and retrievable.
The two groups, and why one is much easier than the other:
| The never-thanked | The long-tenure lapse | |
|---|---|---|
| Who they are | Gave once, often small, no acknowledgement logged | Gave for years, then stopped |
| Usual size of group | Larger than anyone expects | Smaller, and known to the team |
| What went wrong | A process failure, not a decision | Usually a relationship or life change |
| First contact | An apology and a thank-you | A personal call, no ask attached |
| Who should send it | Can be a batch, warmly written | A named person, every time |
| Realistic recovery | Decent, because nobody ever asked them properly | Lower, but each one is worth far more |
That is the practical route. Find the lapsed donors whose last gift was never properly thanked, because an apology and a thank-you is a much easier first contact than a fresh ask. Then work the long-tenure lapses individually, since those are relationships rather than transactions.
Whatever tool you use, insist on seeing the reason attached to each name. A re-engagement list without reasons is just a mail merge.
How does a small development team keep up with stewardship?
By deciding that the constraint is attention, not information, and buying accordingly.
Every organisation I have looked at while writing this cluster has more in its file than anyone has time to read. The bottleneck is not that you lack data on your donors. It is that working out who deserves an hour this week takes an hour you do not have, so it does not happen, and the same twenty familiar names get all the attention while the rest of the file goes quiet.
The realistic fix is to move the triage off your desk and onto something that runs overnight, then spend your actual hours on the conversations. That is the whole argument for this category, and it is why the reason attached to each name matters more than the ranking itself. You need to be able to disagree with the list in five seconds and move on.
One caution, and it has moved. A solo director used to carry the whole five-seat price; now a single fundraiser pays $99 a month and can start free. The awkward case today is two people, who leave the single-person tiers and land on a five-seat plan at $499. The tool does not get less useful at that size, but it does get considerably more expensive per head.
How do I keep donor relationships when a fundraiser leaves?
This is the question I would build the whole purchase around, because it is the one where the architecture does something a CRM cannot.
Your CRM records gifts. It almost never records why someone gives, who introduced them, what they said at the gala, which subject to avoid. That lives in an inbox, a notes field nobody has updated since 2023, and mostly in one person’s head. When they leave, it leaves.
The mechanism that helps is a profile assembled from every source the organisation holds, with citations back to the evidence, so the incoming officer reads a reconstruction from the record rather than somebody’s recollection of it. Gratefully calls the output a handover dossier. I have not generated one, so I am describing the mechanism rather than reviewing the feature.
What I did see is the raw material for it working: a Relationship Narrative for a five-year donor, written from fourteen gift rows, with numbered citations pointing at the specific gifts behind each claim. I checked ten of those claims against the table. All ten were correct.
Two things you can do regardless of software. Make written notes a condition of the job rather than a courtesy, because a tool can only reconstruct what somebody wrote down somewhere. And do the handover before the resignation rather than after, by having every officer produce a portfolio summary annually.
How should I decide who to contact today?
Pick a rule and let it run, rather than deciding fresh each morning, because deciding fresh each morning is how the same twenty names get all the attention.
The rule that seems to drive this product’s ordering blends three things: money at stake, recency of contact, and whether something has just changed. A five-figure donor who has gone quiet outranks a small donor who has gone quiet, and both outrank a healthy donor who simply has not been called in a while.
Worth knowing that Gratefully names the individual jobs behind the ranking rather than hiding them in a single score. The activity log lists each one with the minute it ran:
| Detector | What it is looking for |
|---|---|
| Detect New Donor Signals | A recent donor behaving in a way that is worth noticing early |
| Detect Engagement Spikes | A sudden change in activity, in either direction |
| Detect Trajectory | The direction of travel over time rather than the last gift |
| Detect Stewardship Moments | Anniversaries and milestones that justify warm contact |
| Detect Lapse Risk | The gap between expected and actual giving |
| Detect Deadlines | Dated commitments that are approaching |
| Find Hidden Revenue | Money already implied by the file that nobody has collected |
Seven separate jobs looking for seven different things, not one opaque number. When a card cites two of them, you can see which patterns fired.
There is one design decision worth copying whatever you use. The queue offers Done, Snooze and Dismiss as separate actions. Those mean genuinely different things, handled, not now, and you were wrong, and a system that collapses them into a single button throws away the most useful feedback a fundraiser can give it.
Is it safe to put donor data into ChatGPT?
Not without controls, and this is the question a board will ask you first.
The problem with pasting donor records into a general chatbot is not usually that the vendor is malicious. It is that you have moved names, giving histories and contact details outside your governed systems, into a tool with its own retention and training terms, with no record of what left and no way to get it back.
What a purpose-built tool should do instead is keep the identifying detail out of the model altogether. Gratefully’s stated approach is to tokenize personally identifiable information, names, gift amounts and contact details, before any prompt reaches a language model, then reverse the tokens locally. The model reasons over placeholders. Their line for this is that your data never trains public AI models, and the tokenization is the mechanism that backs the claim rather than merely asserting it.
The difference, put plainly:
| Pasting into a general chatbot | A tool that redacts first | |
|---|---|---|
| What the model sees | Real names, amounts and contact details | Placeholders standing in for them |
| Where the data goes | Outside your governed systems | Identifying fields never leave |
| Training terms | Whatever the consumer product says today | Contractual, and checkable |
| Audit trail | None. You cannot list what was pasted | The connection is the record |
| If you need to stop | The data has already gone | Revoke and export |
I have not audited that implementation, and you should not take my word or theirs for it. But as a stated design it is materially better than the alternative, and it points at the right question to put to any vendor in this space: not “is it secure” but “does the identifying data reach the model at all, and if so under what terms”.
Then ask the four your board will ask. Where is the data stored, how long is it retained, who are the subprocessors, and what happens to it if we leave. On the last one, Gratefully’s pricing page states you can export your knowledge graph at any time, and there is an Export CSV control on the Donors screen, which I confirmed exists.
Can I add AI on top of Bloomerang or Salesforce NPSP without migrating?
Yes, and this is the case the layered approach is built for.
Gratefully connects natively to six systems as of 4 October 2026: Bloomerang, Little Green Light, Salesforce, Mailchimp, HubSpot and Constant Contact. Your CRM stays the system of record, data flows one way, and profiles are read-only reflections of your sources. The product restates that position on three separate screens, which tells you how often it gets asked.
If you are on DonorPerfect, Virtuous, Neon or Blackbaud there is no native connector today and you are on the CSV path. That works, but it is a materially different experience from a live sync, so ask where your platform sits in the queue before you sign anything.
What that means depending on what you run today:
| Your CRM | Native connector | What your week looks like |
|---|---|---|
| Bloomerang | Yes | Live sync, nothing to maintain |
| Little Green Light | Yes | Live sync, nothing to maintain |
| Salesforce / NPSP | Yes | Live sync, the deepest integration of the five |
| Mailchimp | Yes | Engagement data alongside the giving history |
| HubSpot | Yes | Records and marketing email in one connection |
| DonorPerfect | Not yet | CSV export on a schedule you set |
| Virtuous | Not yet | CSV export on a schedule you set |
| Neon | Not yet | CSV export on a schedule you set |
| Blackbaud | Not yet | CSV export on a schedule you set |
Two questions worth putting on the call. How often does the sync run and can you force one. And if you edit a record in the CRM at nine in the morning, when does it appear here. The value of a daily action list depends entirely on the data behind it being current.
How do I find major gift prospects already in my own file?
By looking for capacity you have already been shown, rather than capacity you have to buy data to discover.
The signal is a donor whose giving pattern implies more room than their current level suggests. Several near-equal gifts in a year, which annualises higher than anyone realises. A single large gift in the past that nobody followed up. A steady giver whose interval is tightening.
The product surfaces these as upgrade candidates with the arithmetic attached, in the form “3 near-equal gifts in last 12 months (avg $82, annualized $247)”. A modest example, but the logic is the point: it does the annualisation so the pattern is visible without exporting anything to a spreadsheet.
Be clear about the boundary. This finds capacity visible in your own giving history. It tells you nothing about someone’s property holdings, foundation board seats or public giving elsewhere. That is wealth screening, it is a different product, and DonorSearch is the name in it. Plenty of teams run one for discovery and something like this for daily stewardship.
Is Gratefully worth the money?
That depends almost entirely on how many people will use it.
It depends entirely on how many of you there are. A single fundraiser pays $99 a month, or $79 billed annually, and can start on a free plan that does not expire. A five-person team pays $4,788 a year, which is $80 per person per month for a system that works the whole portfolio overnight, less than many organisations pay per seat for a CRM that only stores the data.
Set it against what it actually replaces. Not another piece of software, but the hours your team spends deciding who to call, and the gifts that quietly do not happen because nobody reached that part of the file. If recovering two mid-level donors a year covers it, the arithmetic is not hard.
Set it against the alternative fix too. Organisations reach for a CRM migration to get better intelligence out of their data. Those run into five figures before anybody is trained, and take months. At $4,788 for a team with no migration, a 14-day trial that costs nothing, and a free tier to fall back to, this is a far cheaper way to find out whether the intelligence was the problem.
Where I would hesitate: a two-person office, where the jump from Essential at $99 to Professional at $499 buys three seats you will not use. And an all-volunteer organisation with no cultivation motion, where there is nobody to hand the daily list to, though that organisation can now sit on the free plan indefinitely and lose nothing by trying.
What is the difference between donor intelligence and a CRM with AI features?
A CRM with AI features is a system of record that has added some generation on top: draft this email, summarise this record, suggest a subject line. The centre of gravity is still storage, and the AI is a convenience layer over data entry.
Donor intelligence points the other way. It assumes your record-keeping is adequate and your attention is not, so its job is to read across everything you hold and tell you where to spend the day. The output is a decision, not a document.
The practical test is what the product does when you open it in the morning. If it shows you a dashboard and waits, it is a CRM. If it shows you a ranked list of people and reasons, it is an intelligence layer.
That distinction also decides whether you can run both. You almost certainly should. Gratefully has no interest in being your system of record, and says so on three separate screens, which means the question is not which one to buy but whether the intelligence layer earns its cost on top of the CRM you already pay for.
21. The seven questions worth asking on the demo call
The price is published, so the call is about fit rather than figures. Most demos run on the vendor’s rails and you leave without the answers you actually needed. Here is what to ask, in the order I would ask it.
1. What does a second seat cost us? Free and Essential are single-person plans, and Professional at $499 a month is the next step up. If there are two or three of you, ask directly whether a seat can be added to Essential, because the published sheet says it cannot and that is the difference between $99 a month and $499.
2. What happens above five seats? Both plans I saw stop at five. If your development team is larger, this is the question that decides whether the product is even available to you, and it is not answerable from the website.
3. Is my CRM natively supported, and if not, what is the CSV workflow in practice? Native support today covers Bloomerang, Little Green Light, Salesforce, Mailchimp and HubSpot. If you are on DonorPerfect, Virtuous, Neon or Blackbaud, ask directly whether a connector is planned and on what timeline, and what your day-to-day looks like until then. A quarterly CSV is a very different product from a live sync.
4. How often does it sync, and can I force one? The value of a daily action list depends entirely on the data behind it being current. Ask what the cadence is on your specific integration and what happens if you update a record in the CRM at nine and want it reflected at ten.
5. Is the Donor Pulse 100-donor cap real, and does it move by plan? Ceilings are what catch buyers out in month four. Get the answer in writing.
6. Ready to Send and Plays: when? If either is central to why you would buy, get a timeframe and decide whether you are buying today’s product or a promise. My advice is to buy the former and treat the latter as upside.
7. What happens to my donor data, specifically? They tokenize PII before anything reaches a language model, which is a good answer and better than most in this category. Push past it anyway: where is the data stored, how long is it retained, who are the subprocessors, and what happens to it if we leave. Those four are what your board will ask you, and it is better to have the answers before the board meeting than during it.
One more, less a question than a request. Ask them to run the demo on your data rather than theirs, even a partial export. Every donor intelligence tool looks impressive on a curated sample set. The interesting moment is when it meets a real file with duplicates, gaps and twenty years of inconsistent data entry, because that is the file you actually have. How the product behaves in that moment tells you more than any feature walkthrough.
22. The verdict
4.7 out of 5.
If your development team carries a donor portfolio, buy the trial. Not the product, the trial. It runs 14 days, needs no credit card and no migration, and it drops to a free plan rather than locking you out when it ends, so it is the only way to find out whether a ranked daily list changes how your week goes. Most tools in this category cannot be evaluated without a sales process. This one can be evaluated on a Tuesday.
That is the recommendation. Here is what it rests on.
I came to this expecting a dashboard and found something closer to an argument. Gratefully makes a specific, testable claim, that every answer is grounded in your data and cites its source, and it is the first product in this category I have been able to put that claim under a microscope and watch it hold.
Ten of ten narrative claims correct against the underlying gift table, including a fourteen-row sum I did on a calculator expecting to catch it out. Two adversarial tests refused cleanly, including a leading question written specifically to invite invention. Lapse arithmetic exact to the dollar. And a habit I have seen nowhere else in this category, of telling you plainly what it does not know.
I want to put that as precisely as I can, because precision is the point. This is the best implementation of source-cited donor intelligence I have tested, and the only product in this category whose central claim I have been able to audit line by line and watch survive. That is not a slogan. It is a description of what I did and what happened, and every step of it is in this article for you to check.
The four tenths I am holding back are not complaints. They are simply the things I could not verify myself. Two significant features are still to come and I do not score unreleased software. There is a ceiling on Donor Pulse I could not test against a 27-donor sample. And the assessment ran on sample data, which means I can tell you the output is internally consistent and correctly sourced but not whether the rankings match a seasoned fundraiser’s instinct. I will revisit the score as those become answerable, and this article is maintained for exactly that reason.
Why I would recommend it to a nonprofit
Four reasons, in the order they would matter to me if I ran a development office.
It answers the question you actually have. Not “what is in my database” but “who do I call today, and what do I say”. Everything else in this category answers the first question and leaves you to work out the second at eight in the morning with a coffee going cold.
You can check its work. Every claim it writes points at the row it came from. That means a sceptical executive director can be handed the reasoning rather than asked to trust a score, which is the difference between a tool the team adopts and a tool the team quietly stops opening.
A full team costs less per head than the CRM underneath it. Professional is $4,788 a year for five people, which is $80 each per month, and there is a free plan under it for anyone who wants to see the reasoning before spending anything. For most organisations that is less than the CRM that merely stores the same data, and far less than the migration somebody has probably proposed as the fix.
Nothing has to change to try it. No migration, no data cleanup first, no implementation project. Connect what you already run, or upload a CSV, and the thing either earns its place inside the trial fortnight or it does not.
Who I would not recommend it to, because a recommendation without a boundary is marketing. An all-volunteer organisation with no cultivation motion, because there is nobody to hand the list to. A two-person office that cannot justify Professional at $499 a month but has outgrown the single-person tiers, which is the one place this pricing still bites. And anyone whose real problem is finding donors they do not have yet, which is wealth screening and a different product entirely.
Disclosure
Written by
FazFaz is the founder of AIToolsBakery. Some tools here are tested hands on. Others are assessed from vendor documentation and pricing verified on the live page, and every review says which one it is. Sponsors can buy a position in a guide. They cannot buy the score, the criticism, or silence about a better option.
How we test and how we make money →